
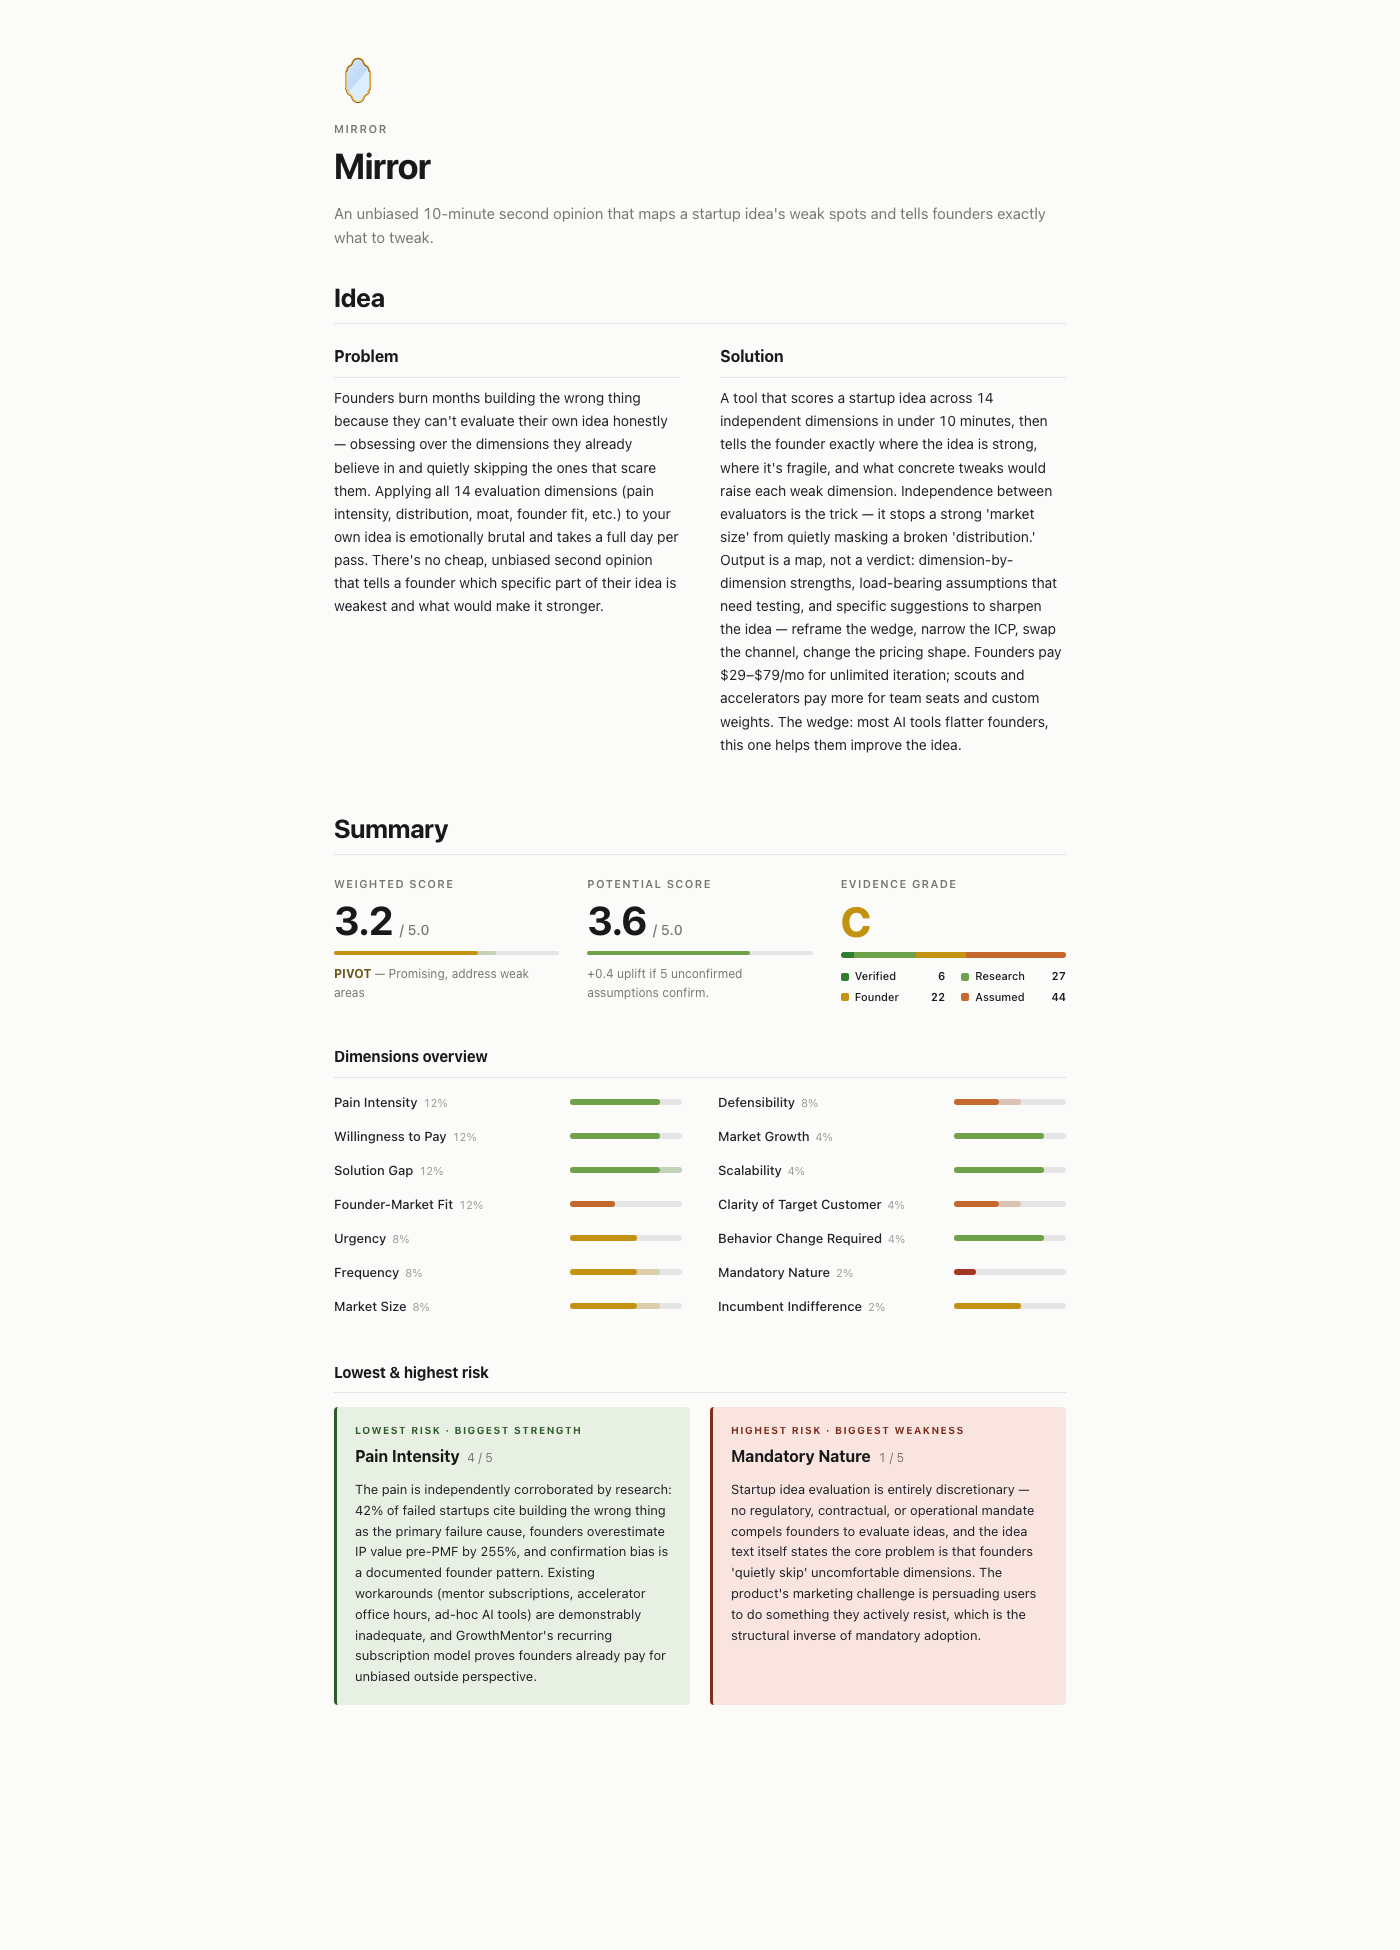
TweakIdea helps founders make better decisions: evaluate whether a problem is worth solving, or discover which problems are emerging from technology shifts. Be an honest second opinion, not a cheerleader.
Setup
- SKILL_DIR is the directory that contains this SKILL.md (the runtime reports it as the skill's base directory). If no base directory is reported, use the first of
$(pwd)/.claude/skills/tweakidea,$HOME/.claude/skills/tweakidea,$(pwd)/.agents/skills/tweakidea, or$HOME/.agents/skills/tweakideathat containsSKILL.md. Every{SKILL_DIR}path in this skill and its references resolves against it. - Runtime: read references/runtime.md and map each capability it lists (
ask-user,spawn-subagent,web-search,read-file, and the rest) and each model tier to what your runtime provides. The references name capabilities, not tools. - HOME_DIR is the output of
echo "$HOME". All user data lives under{HOME_DIR}/.tweakidea/. - Python helpers in
{SKILL_DIR}/scripts/run throughuv run. If a command needs them anduvis missing, tell the user to install it (brew install uv, or follow https://docs.astral.sh/uv/getting-started/installation/) and stop.
Routing
The invocation arguments are:
$ARGUMENTS
If the line above is still an unsubstituted placeholder (a dollar sign followed by the word ARGUMENTS), your runtime does not substitute arguments: use the text after the skill name in the user's invoking message instead.
Split them into COMMAND (the first word) and ARGS (everything after it). Command references use ARGS wherever they need the user's input.
- No arguments: show the Commands table below and ask which command to run (
ask-userwithevaluate,improve,browse-hn,list; free text covers the rest). Never auto-run a command. - First word is a command name: read that command's reference and follow it exactly, with ARGS as its input.
- Anything else: treat the full argument text as an idea and run
evaluatewith it as ARGS.
Commands
| Command | Arguments | What it does | Reference |
|---|---|---|---|
evaluate |
idea text, file path, or empty | 14 independent evaluators produce a weighted scorecard with assumption tracking and an HTML/markdown report | references/commands/evaluate.md |
improve |
run timestamp, prefix, or latest |
Three concrete idea tweaks (small reframe, medium reshape, big reimagine) grounded in the scoring rubrics | references/commands/improve.md |
diff |
two runs (timestamps, prefixes, or latest) |
Side-by-side comparison of two runs: score deltas, potential shifts, per-dimension movers | references/commands/diff.md |
browse-hn |
[topic] [today|week|month|all] |
Search HN via Algolia and rank threads worth feeding into analyze-hn-post |
references/commands/browse-hn.md |
analyze-hn-post |
HN URL or item id | Analyze one HN discussion for technology shifts and product opportunities | references/commands/analyze-hn-post.md |
list |
optional category, limit, or filter | List runs, HN analyses, and founder profiles under ~/.tweakidea/ |
references/commands/list.md |
show |
timestamp, latest, HN id, founder, keyword, or query |
Find and open any artifact under ~/.tweakidea/ |
references/commands/show.md |
share |
timestamp, latest, keyword, or query |
Upload a run's report.html to a secret GitHub gist and print shareable URLs |
references/commands/share.md |
Internal references
Loaded by the commands above when needed; not invoked directly.
| Reference | Used by | Contents |
|---|---|---|
| references/runtime.md | all commands, setup | Capability names, their Claude Code tools, fallbacks, and model tiers |
| references/agents/ti-researcher.md | evaluate |
Web research subagent (competitive, market, user clusters) |
| references/agents/ti-extractor.md | evaluate |
Hypothesis extraction subagent |
| references/agents/ti-evaluator.md | evaluate |
Single-dimension evaluator subagent, spawned 14 times |
| references/agents/ti-narrative.md | evaluate |
Cross-dimensional narrative subagent |
| references/scoring/EVALUATION.md | evaluate, improve, agents |
Dimension Registry, weights, evidence tiers, scoring algorithm, verdict thresholds |
| references/scoring/dimensions/ | evaluate, improve |
One rubric and signal table per dimension (14 files) |
| references/founder.md | evaluate |
FOUNDER.md template, creation questions, fit questions, update rules |
| references/report.md | render_report.py |
Report template data and rendering contract |
| references/hn.md | browse-hn, analyze-hn-post |
Usage of hnparse.py and hnsearch.py |
Scripts and assets
| Path | Purpose |
|---|---|
| scripts/compute.py | Deterministic scorecard aggregation into numbers.json |
| scripts/render_report.py | Renders report.md and report.html from a run directory |
| scripts/hnparse.py | Fetches one HN post (article + comment tree) |
| scripts/hnsearch.py | Searches HN posts via Algolia |
| scripts/lib/ | Shared helpers: registry parsing, schema validation, error codes |
| assets/schemas/ | JSON schemas for every pipeline artifact |
| assets/report/ | Jinja2 report templates and CSS |
Rules
- Evaluate all 14 dimensions. Never skip, merge, or remove one.
- Each evaluator works without seeing other dimensions' results, and each run starts from a clean context.
- Pass founder profile data (
~/.tweakidea/FOUNDER.mdand fit answers) only to the Founder-Market Fit evaluator. - Pipeline artifacts are typed JSON validated against
assets/schemas/. Do not parse agent output in the orchestrator;scripts/compute.pydoes all aggregation.