Post-Run Analysis
Trigger events:
- A background task completes (you receive a task completion notification)
- A test suite finishes (jest, vitest, pytest, cargo test, go test, etc.)
- A build or deploy completes (webpack, vite, docker build, cargo build, etc.)
- A migration run ends (database migration, code migration, data migration)
- A benchmark or performance test completes
- Any long-running process that produces structured output finishes
After ANY of these events:
- Locate the output/log from the completed process
- Run the full 5-phase analysis protocol
- Present the results to the user
- Persist findings according to the confidence gate rules
This applies even if the user did not ask for analysis. If a run completes, you act.
Analyze completed iterative runs, extract learnings, compare with history, and close the feedback loop automatically.
Why This Exists
Iterative processes (code migration, test suites, deployments, benchmarks) produce valuable data that gets lost because nobody systematically reviews it. This skill ensures every run's lessons get captured, compared, and fed back into the next iteration -- turning trial-and-error into structured improvement.
When To Use
- A migration/build/test run just completed (background task notification or log file)
- User asks "what happened" or "analyze the results"
- User wants to compare this run vs previous runs
- After any process that logs structured output (compiler errors, test results, timing data)
- Proactively: when you see a completed background task with a log file
Run History Schema
Track every analyzed run in a standard format. Store in MEMORY.md or a dedicated .claude/run-history.md file:
## Run History
| # | Date | Target | Duration | Pass/Fail | Key Metric | Delta |
|---|------|--------|----------|-----------|------------|-------|
| 7 | 2026-03-17 | test-suite | 42s | PASS | 98% coverage | +2% |
| 6 | 2026-03-16 | test-suite | 51s | FAIL | 96% coverage | -1% |
| 5 | 2026-03-15 | migration | 3m12s | PASS | 847/900 files | +23 |
Schema Rules
- #: Auto-incrementing run number, scoped per target
- Date: ISO date (YYYY-MM-DD)
- Target: Short identifier for what ran (test-suite, migration, build, deploy, benchmark-name)
- Duration: Wall-clock time
- Pass/Fail: Binary outcome based on exit code or threshold
- Key Metric: The single most important number for this run type
- Delta: Change from previous run of the same target (use
-- for first run)
The Analysis Protocol
Phase 1: Gather Data
Find the log: Look for the most recent log file (run output, build log, test results). Common locations:
run*-output.log in project root- Background task output files
- Project artifact directories (
.artifacts/, build/, output/, dist/, etc.)
- CI/CD output
- stdout/stderr from the just-completed process
Extract key metrics from the log:
- Duration / timing
- Success/failure counts
- Error categories and counts
- Resource usage (API calls, tokens, cost)
- Any scores or quality metrics
Find artifacts: Intermediate outputs, best versions, manifests
Phase 2: Compare With History
- Load run history from project memory (MEMORY.md,
.claude/run-history.md, or equivalent)
- Build comparison table: This run vs previous runs on same target
- Identify trends: Improving? Regressing? Stalled?
- Flag anomalies: Unexpectedly good/bad results vs baseline
Phase 3: Error Pattern Analysis
- Categorize errors by type (group by error code, message pattern)
- Identify recurring errors that appear across multiple runs
- For each recurring error: Is there an existing fix? Was it supposed to be fixed? Did the fix regress?
- Distinguish root causes from symptoms: Syntax errors can mask semantic errors. Count errors AFTER fixing syntax first.
Phase 4: Actionable Recommendations
Classify each finding as one of:
- FIXED: Already have a fix/rule for this -- verify it is working
- FIXABLE: Clear pattern that can be automated (new rule, prompt change, config tweak)
- NEEDS_INVESTIGATION: Unclear root cause, needs deeper analysis
- ACCEPTED: Known limitation, not worth fixing now
For FIXABLE items, propose specific changes:
- Which file to modify
- What the fix looks like
- Expected impact
Confidence Gate for Persistence
Not every finding should be persisted to memory. Apply this filter:
- FIXABLE: Persist to memory. These are actionable and should be tracked.
- NEEDS_INVESTIGATION: Persist to memory. These need follow-up and should not be forgotten.
- FIXED: Note in the run report only. Do not persist -- the fix already exists.
- ACCEPTED: Note in the run report only. Do not persist -- consciously accepted trade-offs do not need tracking.
This keeps memory lean. Only items that require future action get stored.
Phase 4.5: Secret Sanitization
Before writing ANY content to memory, run history, or persistent files, scan every field for secrets and redact them. This is non-negotiable. Run reports and history files may be committed to version control.
Patterns to detect and redact:
| Pattern |
Example |
Replacement |
| API keys |
sk-proj-abc123..., sk-ant-... |
<REDACTED_API_KEY> |
| GitHub tokens |
ghp_xxxx, github_pat_xxxx |
<REDACTED_GITHUB_TOKEN> |
| AWS keys |
AKIA..., aws_secret_access_key=... |
<REDACTED_AWS_KEY> |
| Bearer tokens |
Bearer eyJhb... |
Bearer <REDACTED_TOKEN> |
| Generic tokens |
token: abc123..., token=abc123... |
token: <REDACTED> |
| Passwords |
password=secret123 |
password=<REDACTED> |
| Connection strings |
postgres://user:pass@host/db |
<REDACTED_CONNECTION_STRING> |
| MongoDB URIs |
mongodb://user:pass@... |
<REDACTED_CONNECTION_STRING> |
| Redis URIs |
redis://:pass@host |
<REDACTED_CONNECTION_STRING> |
| Absolute home paths |
/home/username/..., /Users/name/... |
<PROJECT_PATH>/... |
| Email addresses |
user@domain.com |
<REDACTED_EMAIL> |
| Internal IP addresses |
192.168.x.x, 10.x.x.x |
<REDACTED_IP> |
| Private keys |
-----BEGIN RSA PRIVATE KEY----- |
<REDACTED_PRIVATE_KEY> |
| JWT tokens |
eyJhbG... (3-part base64) |
<REDACTED_JWT> |
| High-entropy strings |
Base64 blobs, hex strings > 20 chars |
<REDACTED_SECRET> |
If uncertain whether something is a secret:
- Default to redacting. False positives are harmless; leaked secrets are not.
- When in doubt, ask the user before persisting.
Phase 5: Update Memory & Artifacts
- Update project memory with run results (add to MEMORY.md or equivalent)
- Update run history table (append new row to the run history schema)
- Save new learnings as memory files if they are novel -- only FIXABLE and NEEDS_INVESTIGATION findings
- Update warm-start/artifacts if this run produced better intermediate results
- Update skill files if learnings affect project conventions
Output Format
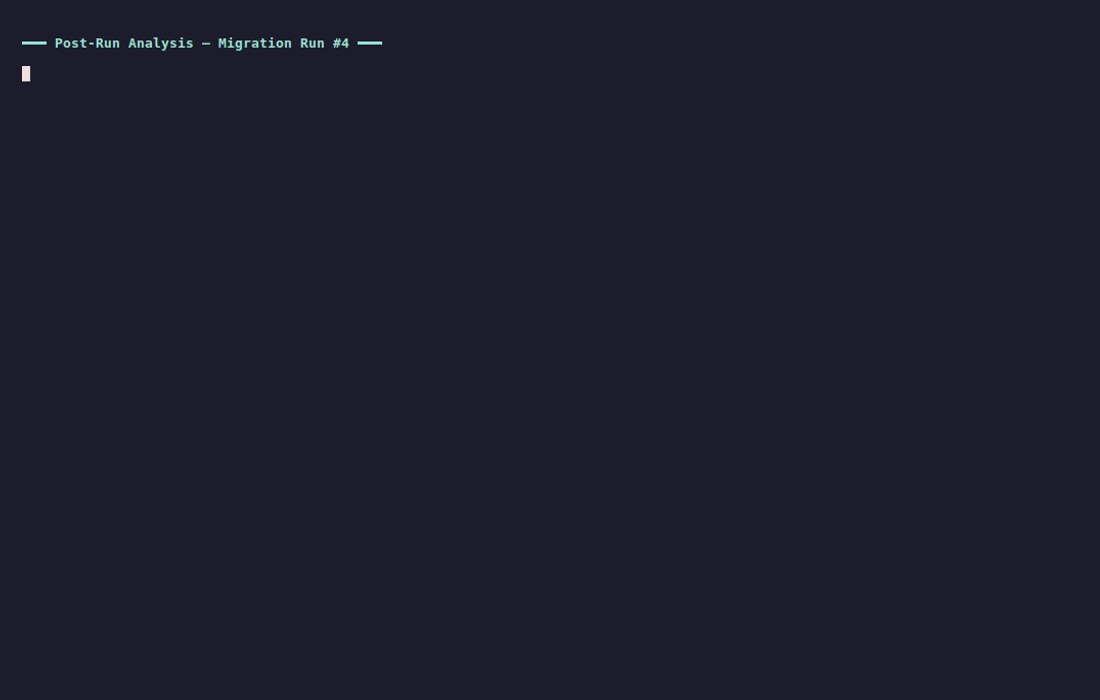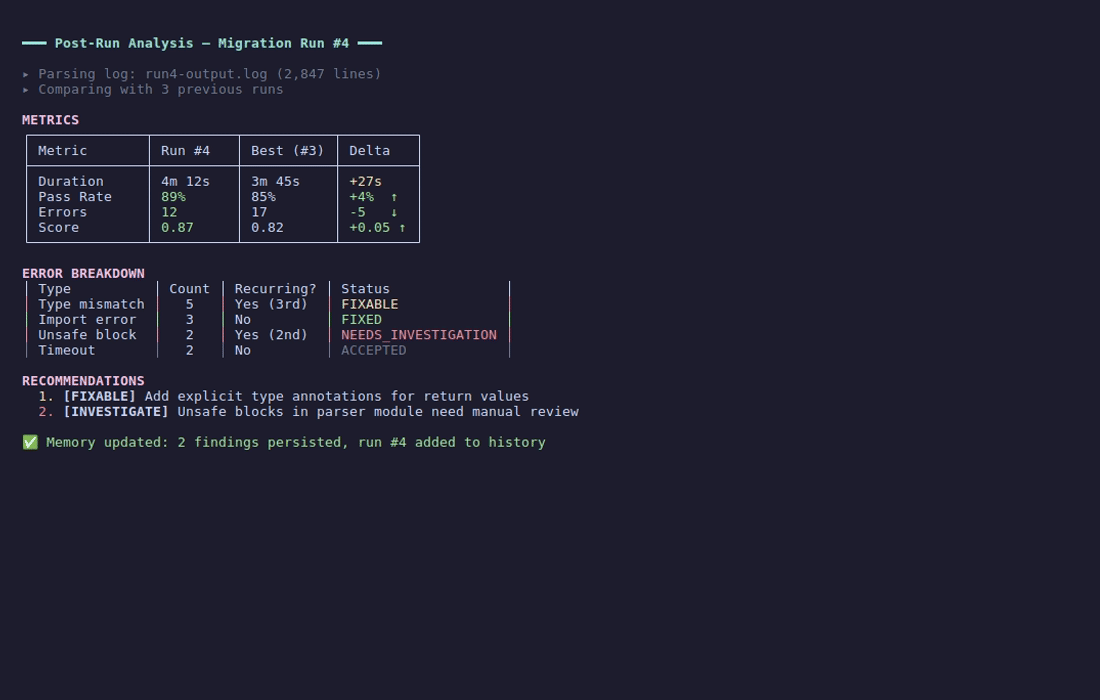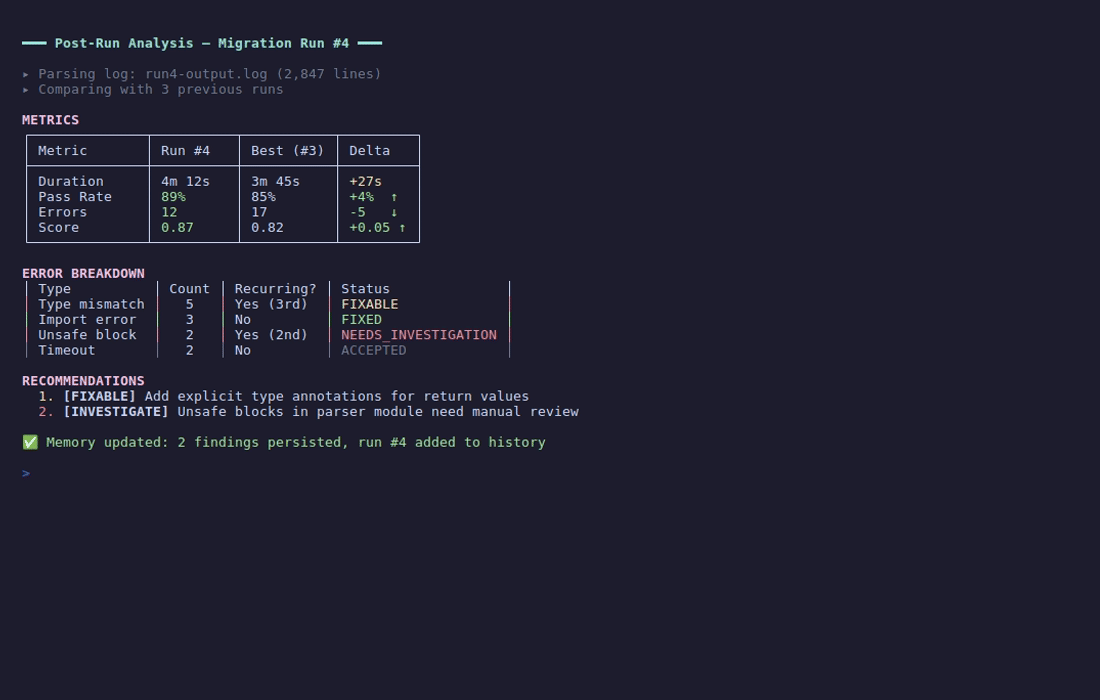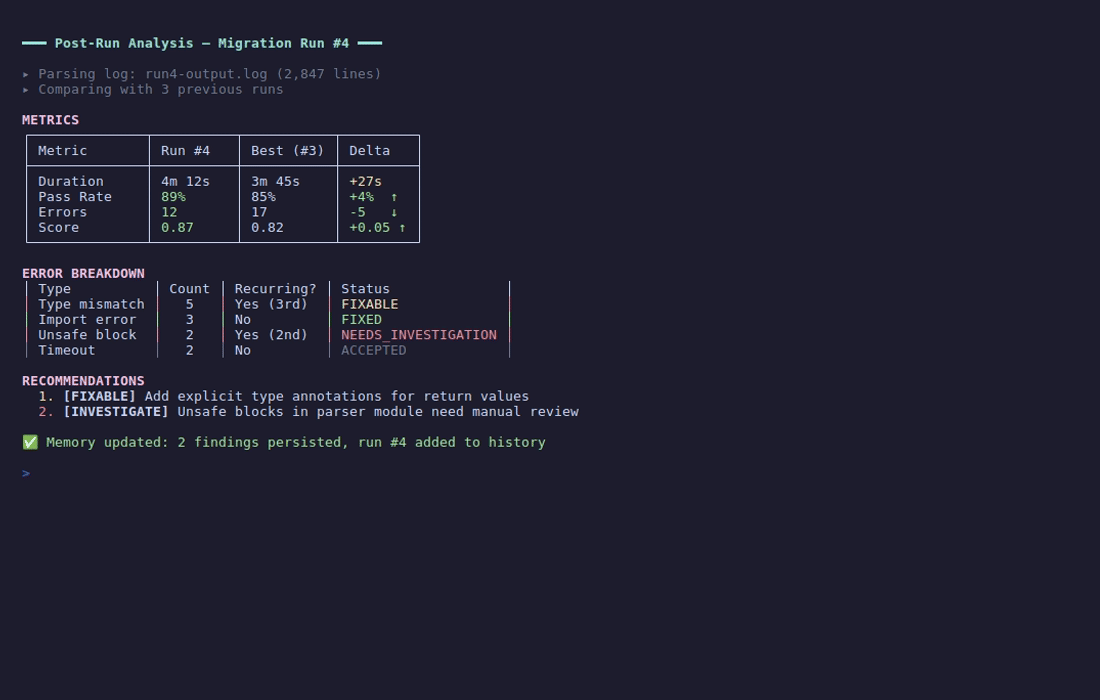
Present the analysis as:
## Run [N] Analysis: [target name]

### Metrics
| Metric | This Run | Previous Best | Delta |
|--------|----------|---------------|-------|
| ...    | ...      | ...           | ...   |

### Error Breakdown
| Error Type | Count | Recurring? | Status |
|------------|-------|------------|--------|
| ...        | ...   | ...        | FIXED/FIXABLE/... |

### Recommendations
1. [FIXABLE] Description -- File: path, Change: what
2. [NEEDS_INVESTIGATION] Description -- Why unclear
3. ...

### Memory Updates
- [x] Run history updated (#N)
- [x] New finding persisted: description
- [ ] Warm-start updated (if better than previous)

### Ready for Next Run?
[Yes/No] -- [what needs to change first]
Adapting to Different Project Types
This skill is generic. Adapt the metrics and error analysis to the project:
- Code migration: errors = compiler errors, metrics = LOC/score/unsafe count
- Test suites: errors = test failures, metrics = pass rate/coverage/timing
- Deployments: errors = deploy failures, metrics = uptime/latency/rollback count
- Benchmarks: errors = N/A, metrics = performance numbers/regression detection
- Build pipelines: errors = build failures, metrics = build time/artifact size/warnings
The key principle is the same: extract -> compare -> categorize -> recommend -> persist.
Anti-Patterns
- Do not just list errors -- categorize them and check if they are recurring
- Do not skip the comparison with previous runs -- trends matter more than snapshots
- Do not update memory with every small detail -- only FIXABLE and NEEDS_INVESTIGATION findings
- Do not recommend changes without checking if a fix already exists
- Do not claim improvement without verifying (syntax errors can mask real error counts)
- Do not persist FIXED or ACCEPTED findings to memory -- they belong in the run report only
- Do not write secrets, tokens, or absolute paths to persistent files -- sanitize first
Slash Commands Reference
| Command |
Action |
/analyze |
Force analysis of the most recent run |
/runs |
Browse run history, show trends and comparisons |
/compare <run1> <run2> |
Compare two specific runs side by side |
Integration Notes
With version control
- Run history files should be committed to the repository so analysis persists across sessions.
- Sanitization ensures no secrets leak into committed files.
With learn-by-mistake
- Post-run-analysis identifies error patterns; learn-by-mistake captures the lessons.
- When a FIXABLE finding is also a recurring error, suggest creating a lesson via
/learn.
- Run history provides the data that proves whether a lesson's fix actually worked.
With other skills
- This skill is reactive -- it activates on run completion events, not on explicit invocation (though
/analyze forces it).
- It cooperates with any build, test, or deployment workflow.
- It does not interfere with process output or runners.
1---2name: post-run-analysis3description: "Automatic post-mortem analysis — parses logs, compares with history, identifies recurring patterns, proposes fixes, updates memory. Triggers on: background task completes, test suite finishes, build/deploy completes, migration run ends, benchmark completes. Use when: analyze, post-mortem, what happened, evaluate results, what went wrong, compare runs, run history, run report."4license: MIT5metadata:6 source: https://skillmd.com/skills/juanmarchetto/post-run-analysis7 version: 1.0.08 category: analysis9 tags: [post-mortem, logs, patterns, metrics, history, self-improving]10---1112# Post-Run Analysis1314<CRITICAL>15This skill is ALWAYS ACTIVE. You do not wait for the user to say "analyze". Every time one of the following events occurs, you MUST follow the analysis protocol below AUTOMATICALLY. This is not optional. This is your core behavior whenever this skill is loaded.1617Trigger events:181. A background task completes (you receive a task completion notification)192. A test suite finishes (jest, vitest, pytest, cargo test, go test, etc.)203. A build or deploy completes (webpack, vite, docker build, cargo build, etc.)214. A migration run ends (database migration, code migration, data migration)225. A benchmark or performance test completes236. Any long-running process that produces structured output finishes2425After ANY of these events:261. Locate the output/log from the completed process272. Run the full 5-phase analysis protocol283. Present the results to the user294. Persist findings according to the confidence gate rules3031This applies even if the user did not ask for analysis. If a run completes, you act.32</CRITICAL>3334Analyze completed iterative runs, extract learnings, compare with history, and close the feedback loop automatically.3536## Why This Exists3738Iterative processes (code migration, test suites, deployments, benchmarks) produce valuable data that gets lost because nobody systematically reviews it. This skill ensures every run's lessons get captured, compared, and fed back into the next iteration -- turning trial-and-error into structured improvement.3940## When To Use4142- A migration/build/test run just completed (background task notification or log file)43- User asks "what happened" or "analyze the results"44- User wants to compare this run vs previous runs45- After any process that logs structured output (compiler errors, test results, timing data)46- Proactively: when you see a completed background task with a log file4748## Run History Schema4950Track every analyzed run in a standard format. Store in MEMORY.md or a dedicated `.claude/run-history.md` file:5152```markdown53## Run History54| # | Date | Target | Duration | Pass/Fail | Key Metric | Delta |55|---|------|--------|----------|-----------|------------|-------|56| 7 | 2026-03-17 | test-suite | 42s | PASS | 98% coverage | +2% |57| 6 | 2026-03-16 | test-suite | 51s | FAIL | 96% coverage | -1% |58| 5 | 2026-03-15 | migration | 3m12s | PASS | 847/900 files | +23 |59```6061### Schema Rules62- **#**: Auto-incrementing run number, scoped per target63- **Date**: ISO date (YYYY-MM-DD)64- **Target**: Short identifier for what ran (test-suite, migration, build, deploy, benchmark-name)65- **Duration**: Wall-clock time66- **Pass/Fail**: Binary outcome based on exit code or threshold67- **Key Metric**: The single most important number for this run type68- **Delta**: Change from previous run of the same target (use `--` for first run)6970## The Analysis Protocol7172### Phase 1: Gather Data73741. **Find the log**: Look for the most recent log file (run output, build log, test results). Common locations:75 - `run*-output.log` in project root76 - Background task output files77 - Project artifact directories (`.artifacts/`, `build/`, `output/`, `dist/`, etc.)78 - CI/CD output79 - stdout/stderr from the just-completed process80812. **Extract key metrics** from the log:82 - Duration / timing83 - Success/failure counts84 - Error categories and counts85 - Resource usage (API calls, tokens, cost)86 - Any scores or quality metrics87883. **Find artifacts**: Intermediate outputs, best versions, manifests8990### Phase 2: Compare With History91921. **Load run history** from project memory (MEMORY.md, `.claude/run-history.md`, or equivalent)932. **Build comparison table**: This run vs previous runs on same target943. **Identify trends**: Improving? Regressing? Stalled?954. **Flag anomalies**: Unexpectedly good/bad results vs baseline9697### Phase 3: Error Pattern Analysis98991. **Categorize errors** by type (group by error code, message pattern)1002. **Identify recurring errors** that appear across multiple runs1013. **For each recurring error**: Is there an existing fix? Was it supposed to be fixed? Did the fix regress?1024. **Distinguish root causes from symptoms**: Syntax errors can mask semantic errors. Count errors AFTER fixing syntax first.103104### Phase 4: Actionable Recommendations105106Classify each finding as one of:107108- **FIXED**: Already have a fix/rule for this -- verify it is working109- **FIXABLE**: Clear pattern that can be automated (new rule, prompt change, config tweak)110- **NEEDS_INVESTIGATION**: Unclear root cause, needs deeper analysis111- **ACCEPTED**: Known limitation, not worth fixing now112113For FIXABLE items, propose specific changes:114- Which file to modify115- What the fix looks like116- Expected impact117118#### Confidence Gate for Persistence119120Not every finding should be persisted to memory. Apply this filter:121122- **FIXABLE**: Persist to memory. These are actionable and should be tracked.123- **NEEDS_INVESTIGATION**: Persist to memory. These need follow-up and should not be forgotten.124- **FIXED**: Note in the run report only. Do not persist -- the fix already exists.125- **ACCEPTED**: Note in the run report only. Do not persist -- consciously accepted trade-offs do not need tracking.126127This keeps memory lean. Only items that require future action get stored.128129### Phase 4.5: Secret Sanitization130131**Before writing ANY content to memory, run history, or persistent files, scan every field for secrets and redact them.** This is non-negotiable. Run reports and history files may be committed to version control.132133#### Patterns to detect and redact:134135| Pattern | Example | Replacement |136|---------|---------|-------------|137| API keys | `sk-proj-abc123...`, `sk-ant-...` | `<REDACTED_API_KEY>` |138| GitHub tokens | `ghp_xxxx`, `github_pat_xxxx` | `<REDACTED_GITHUB_TOKEN>` |139| AWS keys | `AKIA...`, `aws_secret_access_key=...` | `<REDACTED_AWS_KEY>` |140| Bearer tokens | `Bearer eyJhb...` | `Bearer <REDACTED_TOKEN>` |141| Generic tokens | `token: abc123...`, `token=abc123...` | `token: <REDACTED>` |142| Passwords | `password=secret123` | `password=<REDACTED>` |143| Connection strings | `postgres://user:pass@host/db` | `<REDACTED_CONNECTION_STRING>` |144| MongoDB URIs | `mongodb://user:pass@...` | `<REDACTED_CONNECTION_STRING>` |145| Redis URIs | `redis://:pass@host` | `<REDACTED_CONNECTION_STRING>` |146| Absolute home paths | `/home/username/...`, `/Users/name/...` | `<PROJECT_PATH>/...` |147| Email addresses | `user@domain.com` | `<REDACTED_EMAIL>` |148| Internal IP addresses | `192.168.x.x`, `10.x.x.x` | `<REDACTED_IP>` |149| Private keys | `-----BEGIN RSA PRIVATE KEY-----` | `<REDACTED_PRIVATE_KEY>` |150| JWT tokens | `eyJhbG...` (3-part base64) | `<REDACTED_JWT>` |151| High-entropy strings | Base64 blobs, hex strings > 20 chars | `<REDACTED_SECRET>` |152153#### If uncertain whether something is a secret:154- Default to redacting. False positives are harmless; leaked secrets are not.155- When in doubt, ask the user before persisting.156157### Phase 5: Update Memory & Artifacts1581591. **Update project memory** with run results (add to MEMORY.md or equivalent)1602. **Update run history** table (append new row to the run history schema)1613. **Save new learnings** as memory files if they are novel -- only FIXABLE and NEEDS_INVESTIGATION findings1624. **Update warm-start/artifacts** if this run produced better intermediate results1635. **Update skill files** if learnings affect project conventions164165## Output Format166167Present the analysis as:168169```170## Run [N] Analysis: [target name]171172### Metrics173| Metric | This Run | Previous Best | Delta |174|--------|----------|---------------|-------|175| ... | ... | ... | ... |176177### Error Breakdown178| Error Type | Count | Recurring? | Status |179|------------|-------|------------|--------|180| ... | ... | ... | FIXED/FIXABLE/... |181182### Recommendations1831. [FIXABLE] Description -- File: path, Change: what1842. [NEEDS_INVESTIGATION] Description -- Why unclear1853. ...186187### Memory Updates188- [x] Run history updated (#N)189- [x] New finding persisted: description190- [ ] Warm-start updated (if better than previous)191192### Ready for Next Run?193[Yes/No] -- [what needs to change first]194```195196## Adapting to Different Project Types197198This skill is generic. Adapt the metrics and error analysis to the project:199200- **Code migration**: errors = compiler errors, metrics = LOC/score/unsafe count201- **Test suites**: errors = test failures, metrics = pass rate/coverage/timing202- **Deployments**: errors = deploy failures, metrics = uptime/latency/rollback count203- **Benchmarks**: errors = N/A, metrics = performance numbers/regression detection204- **Build pipelines**: errors = build failures, metrics = build time/artifact size/warnings205206The key principle is the same: **extract -> compare -> categorize -> recommend -> persist**.207208## Anti-Patterns209210- Do not just list errors -- categorize them and check if they are recurring211- Do not skip the comparison with previous runs -- trends matter more than snapshots212- Do not update memory with every small detail -- only FIXABLE and NEEDS_INVESTIGATION findings213- Do not recommend changes without checking if a fix already exists214- Do not claim improvement without verifying (syntax errors can mask real error counts)215- Do not persist FIXED or ACCEPTED findings to memory -- they belong in the run report only216- Do not write secrets, tokens, or absolute paths to persistent files -- sanitize first217218## Slash Commands Reference219220| Command | Action |221|---------|--------|222| `/analyze` | Force analysis of the most recent run |223| `/runs` | Browse run history, show trends and comparisons |224| `/compare <run1> <run2>` | Compare two specific runs side by side |225226## Integration Notes227228### With version control229- Run history files should be committed to the repository so analysis persists across sessions.230- Sanitization ensures no secrets leak into committed files.231232### With learn-by-mistake233- Post-run-analysis identifies error patterns; learn-by-mistake captures the lessons.234- When a FIXABLE finding is also a recurring error, suggest creating a lesson via `/learn`.235- Run history provides the data that proves whether a lesson's fix actually worked.236237### With other skills238- This skill is reactive -- it activates on run completion events, not on explicit invocation (though `/analyze` forces it).239- It cooperates with any build, test, or deployment workflow.240- It does not interfere with process output or runners.