SkillEvaluator
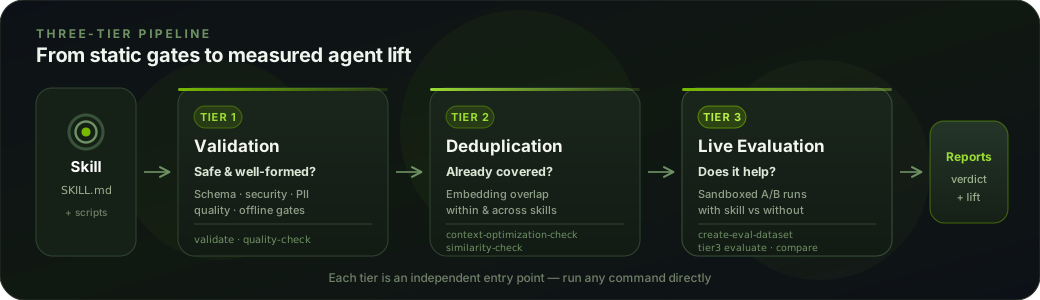
Run the SkillEvaluator CLI on agent skills and report what the evidence shows:
Tier 1 validation (static, security, quality), Tier 2 deduplication, and Tier 3
live agent evaluation that compares runs with and without the skill.
Purpose
Give an agent one reliable procedure for evaluating skills with
SkillEvaluator: pick the right tier, check readiness, run it, and report
scores, findings and exit codes truthfully.
When To Use
Use this skill when the user wants to:
- check whether a skill is well-formed, safe, and good enough to publish
- get a quality score, rubric score, security or PII scan for a skill
- find repeated guidance inside a skill or overlap across a skill collection
- measure whether a skill actually helps an agent (Skill Lift, pass@k)
- write or fix
<skill-dir>/evals/evals.json, <skill-dir>/evals/config.yml, custom graders, or Harbor tasks
- read a SkillEvaluator report, verdict, or exit code
- add SkillEvaluator checks to GitHub Actions or GitLab CI
Do not use it to write the target skill's domain content, to review ordinary
application code, or to evaluate an LLM without a skill. For converting an
existing benchmark into a custom grader, read
references/custom-graders.md.
Prerequisites
- A target directory containing
SKILL.md (or a folder of skills, .mdc
rules, or a plugin manifest).
- The CLI on Python 3.12-3.14. If it is missing, install it yourself (Workflow
step 1). Extras:
llm (rubric), security (scanners), tier2, tier3,
all, dashboard. From a source checkout use
uv run --python 3.13 --extra all skillevaluator ....
- No key for keyless commands (
quality-check, security-scan, pii-scan,
lint-scripts, tier1 PATH --no-llm, validate PATH --tiers 1).
- A provider for LLM stages, Tier 2 and Tier 3. Simplest:
export SKILL_EVAL_LLM_PROVIDER=nv_build and export NVIDIA_API_KEY=....
Other providers: references/providers.md.
- For Tier 3: an agent (
opencode, codex, or claude-code) and a sandbox.
Harbor is installed with the tier3 extra; you do not run it yourself.
The default --env-mode docker needs a Docker daemon. Without Docker, use
--env-mode local (experimental): it runs the agent CLI already installed
on the host under Bubblewrap (Linux) or Seatbelt (macOS); trusted skills only.
Never print, echo, or commit API keys; keep them in the host environment.
Choose The Command
| User goal |
Command |
Needs |
| Fast keyless quality score |
skillevaluator quality-check <skill-dir> |
nothing |
| Full static gate for one skill |
skillevaluator tier1 <skill-dir> --no-llm |
scanners (auto-installed) |
| Static gate plus LLM rubric and security review |
skillevaluator tier1 <skill-dir> |
provider |
| LLM rubric only |
skillevaluator rubric-eval <skill-dir> |
provider, llm extra |
| Security / PII scan only |
skillevaluator security-scan <skill-dir>, skillevaluator pii-scan <skill-dir> |
nothing |
| Repeated content inside one skill |
skillevaluator tier2 <skill-dir> |
provider with embeddings |
| Overlap across a collection |
skillevaluator similarity-check <skills-dir> |
embeddings |
| Does the skill help an agent? |
skillevaluator tier3 <skill-dir> |
provider, agent, Docker |
| Same, without Docker |
skillevaluator tier3 evaluate <skill-dir> -a opencode --env-mode local |
provider, agent CLI on host |
| Everything, with one exit code |
skillevaluator validate <skill-dir> |
all of the above |
| CI-safe keyless gate |
skillevaluator validate <skills-dir> --profile default --tiers 1 -r json,markdown,sarif -o reports |
scanners |
| Set up repo CI |
skillevaluator ci init |
GitHub checkout |
Full flag tables: Tier 1,
validate,
Tier 2, Tier 3 and setup.
Workflow
Get the CLI. Run skillevaluator --version. If the command is not
found, install it in the first way that works, then run the version check
again:
uv tool install --python 3.13 "skillevaluator[all]" (isolated, preferred)pipx install "skillevaluator[all]"python3 -m pip install --upgrade "skillevaluator[all]" inside an active
virtual environment- with no install, prefix each command with
uvx --python 3.13 --from "skillevaluator[all]"
Ask the user before installing into a system or shared Python; never use
sudo pip. If the binary is installed but not on PATH, run
uv tool update-shell or add ~/.local/bin to PATH. If a documented
command or flag is unknown, upgrade: uv tool upgrade skillevaluator. If
installation fails (no network, no Python 3.12+), stop and report the
exact error and the install command instead of guessing results.
Locate the target. Confirm the path has SKILL.md and that its
frontmatter name matches the directory name. For a folder of skills, the
commands evaluate each skill inside it.
Check readiness before paid runs. Run skillevaluator health-check --tier 1
for scanners, skillevaluator doctor --tier 2 for providers, and
skillevaluator doctor --env-mode docker (add --verify-models) for Tier 3.
Fix every failing row first.
Start keyless. Run skillevaluator tier1 <skill-dir> --no-llm. Fix
CRITICAL and HIGH findings before anything else; lint findings are advisory.
Add LLM checks when a provider is set: skillevaluator tier1 <skill-dir>
(rubric, LLM security, verification) and skillevaluator tier2 <skill-dir>.
Prepare Tier 3 cases. If <skill-dir>/evals/evals.json is missing, first
capture task requests and observable outcomes in <skill-dir>/evals/EVAL.md;
headings alone do not qualify. Generate with
skillevaluator create-eval-dataset <skill-dir> --full --prompt <skill-dir>/evals/EVAL.md,
then review it. The default prefers author guidance, then matching retained
traces; existing datasets need --force or --refine. Skill-only
generation requires explicit opt-in with --grounding skill. Review:
positive cases (explicit, implicit, contextual) and at least one negative
case with "expected_skill": null. Required shape: top-level skill_name
and an evals array; each case has id, prompt, expected_output, and
expected_skill (optional assertions, files). Validate with
skillevaluator tier3 validate <skill-dir> --strict. Format:
references/tier3-datasets.md; run policy and
scoring: references/tier3-running.md.
Run live evaluation. skillevaluator tier3 <skill-dir> (or
skillevaluator tier3 evaluate <skill-dir> -a opencode --env-mode docker --n-attempts 3).
Use --max-cases 1 for a cheap smoke run first; such runs are never
publication evidence.
Read the results (see below), open skillevaluator view <skill-dir>, and
for follow-up questions run skillevaluator tier3 feedback <run-dir>.
Iterate. Change the skill, rerun the same command with the same cases,
agent and model, and compare. Treat a single run's lift as directional.
Read The Results
Exit codes: 0 success, 1 a gate failed, evidence is INCOMPLETE, or the
run could not complete, 2 usage error (bad flag or missing path; fix the
command, not the skill).
- Quality (0-100): Correctness 35%, Discoverability 25%, Reliability 25%,
Efficiency 15%. Grades A>=90, B>=80, C>=70. Passing needs
--min-score
(default 70) and no HIGH/CRITICAL quality finding.
- Rubric (0-100): nine criteria scored 0-10; passing needs the weighted
score >=
--min-score and every criterion >= 7.
- Tier 2: HIGH or CRITICAL duplicate findings exit
1 in tier2 PATH.
- Tier 3: five dimensions (Security, Correctness, Discoverability,
Effectiveness, Efficiency), each PASS >= 0.50, NEUTRAL 0.40-0.50, FAIL < 0.40.
Verdict PASS needs every dimension >= 0.50 for at least one agent. Skill
Lift = with-skill overall - baseline overall; PASS >= +0.05.
INCONCLUSIVE: skill never activated means no positive trial loaded the skill; fix the
description or prompts, not the scores. tier3 PATH exits 0 on a FAIL
verdict; only an incomplete run exits 1.
- Missing scores are
NO SCORE or None, never 0. Do not average them in.
- Publication: require
publication_status == "pass" in the JSON report,
not just overall_passed.
Report anatomy and JSON fields: references/reports-and-ci.md.
Examples
# Keyless first look
skillevaluator quality-check <skill-dir> -r cli -r json -o <report-dir>

# Static gate for a whole collection, complete report even on failures
skillevaluator validate <skills-dir> --profile default --tiers 1 -c -r json,markdown -o reports

# LLM-backed Tier 1 and Tier 2, dedup advisory
skillevaluator validate <skill-dir> --tiers 1,2 --llm --no-block-on-dedup

# Live A/B evaluation with two agents, retaining trajectories for debugging
skillevaluator tier3 evaluate <skill-dir> -a opencode,codex --n-attempts 3 --harbor-keep-jobs

# Baseline only, to calibrate cases before the skill exists
skillevaluator tier3 evaluate <skill-dir> --skip-with-skill
Limitations
- Tier 1 and the quality score are static: they check structure and wording,
not whether the skill works. Only Tier 3 observes agent behavior.
- LLM judges (rubric, Tier 3 correctness/effectiveness) vary between runs and
models; compare runs only with the same model, cases, and attempts.
- Tier 3 costs model tokens and sandbox time per case x attempt x agent x 2
arms; a generated starter case gives limited coverage.
validate --tiers always includes Tier 1; --tiers 2 or --tiers 3 alone is
rejected. Use tier2 PATH or tier3 PATH to run a tier on its own.- Agent credentials come only from the host environment;
<skill-dir>/evals/config.yml
runtime_env rejects provider keys.
Troubleshooting
| Symptom |
Cause |
Fix |
skillevaluator: command not found |
CLI not installed or not on PATH |
Workflow step 1: install with uv tool install, pipx, or pip in a virtual environment, or use uvx |
Exit 2 |
Unknown flag, bad value, or missing path |
Check skillevaluator <command> --help; prefix paths named like commands with ./ |
Check shows INCOMPLETE |
A scanner is missing or failed |
Run skillevaluator health-check --tier 1; install the security extra or the missing scanner |
"provider is required" / exit 1 before reports |
No SKILL_EVAL_LLM_PROVIDER or key, or several keys exported |
Set exactly one provider and its key; see providers reference |
| Quality below 70 |
Missing ## Prerequisites, ## Limitations, ## Troubleshooting, vague description, no examples |
Read each finding's suggestion; do not stuff keywords |
INCONCLUSIVE: skill never activated |
Description does not match the prompts |
Make the description name the tasks; add explicit-bucket cases |
| Docker trials fail to start |
Daemon down or outdated engine |
docker info; rerun skillevaluator doctor --env-mode docker |
| Agent model rejected |
Default model not valid for that agent |
--agent-model AGENT=MODEL, verify with doctor --verify-models |
Run incomplete (Scored attempt coverage is n/m) |
A trial errored or timed out |
Rerun; raise --timeout-multiplier; inspect with --harbor-keep-jobs |
More cases: references/troubleshooting.md.
Final Response
Report to the user:
- the exact commands run and their exit codes
- scores and verdicts per tier, quoting the report values (not estimates)
- the top findings to fix, each with its file and suggested change
- report paths (
<report-dir>/..., <skill-dir>/evals/results/<run-id>/report.html)
- what was not run (skipped tiers, missing keys,
--max-cases smoke runs) and
therefore not proven
1---2name: skillevaluator3description: Run and interpret SkillEvaluator for agent skills. Use for any skill benchmark or eval - validating or scoring a SKILL.md, writing evals.json test cases or evals config, explaining benchmark reports, verdicts and exit codes, or gating skills in CI.4license: Apache-2.05compatibility: Requires Python 3.12-3.14 and the skillevaluator CLI; live evaluation also needs Docker (or another backend) and an LLM provider key.6metadata:7 source: https://skillmd.com/skills/nvidia/skillevaluator8 author: Christopher Kevin <christopherk@nvidia.com>9 version: "1.0.0"10 domain: [evaluation, ai-ml]11 tags: [skills, evaluation, benchmarking, ci, security]12---1314# SkillEvaluator1516Run the SkillEvaluator CLI on agent skills and report what the evidence shows:17Tier 1 validation (static, security, quality), Tier 2 deduplication, and Tier 318live agent evaluation that compares runs with and without the skill.1920## Purpose2122Give an agent one reliable procedure for evaluating skills with23SkillEvaluator: pick the right tier, check readiness, run it, and report24scores, findings and exit codes truthfully.2526## When To Use2728Use this skill when the user wants to:2930- check whether a skill is well-formed, safe, and good enough to publish31- get a quality score, rubric score, security or PII scan for a skill32- find repeated guidance inside a skill or overlap across a skill collection33- measure whether a skill actually helps an agent (Skill Lift, pass@k)34- write or fix `<skill-dir>/evals/evals.json`, `<skill-dir>/evals/config.yml`, custom graders, or Harbor tasks35- read a SkillEvaluator report, verdict, or exit code36- add SkillEvaluator checks to GitHub Actions or GitLab CI3738Do not use it to write the target skill's domain content, to review ordinary39application code, or to evaluate an LLM without a skill. For converting an40existing benchmark into a custom grader, read41[references/custom-graders.md](references/custom-graders.md).4243## Prerequisites4445- A target directory containing `SKILL.md` (or a folder of skills, `.mdc`46 rules, or a plugin manifest).47- The CLI on Python 3.12-3.14. If it is missing, install it yourself (Workflow48 step 1). Extras: `llm` (rubric), `security` (scanners), `tier2`, `tier3`,49 `all`, `dashboard`. From a source checkout use50 `uv run --python 3.13 --extra all skillevaluator ...`.51- No key for keyless commands (`quality-check`, `security-scan`, `pii-scan`,52 `lint-scripts`, `tier1 PATH --no-llm`, `validate PATH --tiers 1`).53- A provider for LLM stages, Tier 2 and Tier 3. Simplest:54 `export SKILL_EVAL_LLM_PROVIDER=nv_build` and `export NVIDIA_API_KEY=...`.55 Other providers: [references/providers.md](references/providers.md).56- For Tier 3: an agent (`opencode`, `codex`, or `claude-code`) and a sandbox.57 Harbor is installed with the `tier3` extra; you do not run it yourself.58 The default `--env-mode docker` needs a Docker daemon. Without Docker, use59 `--env-mode local` (experimental): it runs the agent CLI already installed60 on the host under Bubblewrap (Linux) or Seatbelt (macOS); trusted skills only.6162Never print, echo, or commit API keys; keep them in the host environment.6364## Choose The Command6566| User goal | Command | Needs |67| --- | --- | --- |68| Fast keyless quality score | `skillevaluator quality-check <skill-dir>` | nothing |69| Full static gate for one skill | `skillevaluator tier1 <skill-dir> --no-llm` | scanners (auto-installed) |70| Static gate plus LLM rubric and security review | `skillevaluator tier1 <skill-dir>` | provider |71| LLM rubric only | `skillevaluator rubric-eval <skill-dir>` | provider, `llm` extra |72| Security / PII scan only | `skillevaluator security-scan <skill-dir>`, `skillevaluator pii-scan <skill-dir>` | nothing |73| Repeated content inside one skill | `skillevaluator tier2 <skill-dir>` | provider with embeddings |74| Overlap across a collection | `skillevaluator similarity-check <skills-dir>` | embeddings |75| Does the skill help an agent? | `skillevaluator tier3 <skill-dir>` | provider, agent, Docker |76| Same, without Docker | `skillevaluator tier3 evaluate <skill-dir> -a opencode --env-mode local` | provider, agent CLI on host |77| Everything, with one exit code | `skillevaluator validate <skill-dir>` | all of the above |78| CI-safe keyless gate | `skillevaluator validate <skills-dir> --profile default --tiers 1 -r json,markdown,sarif -o reports` | scanners |79| Set up repo CI | `skillevaluator ci init` | GitHub checkout |8081Full flag tables: [Tier 1](references/commands-tier1.md),82[validate](references/commands-validate.md),83[Tier 2, Tier 3 and setup](references/commands-tier2-tier3.md).8485## Workflow86871. **Get the CLI.** Run `skillevaluator --version`. If the command is not88 found, install it in the first way that works, then run the version check89 again:90 - `uv tool install --python 3.13 "skillevaluator[all]"` (isolated, preferred)91 - `pipx install "skillevaluator[all]"`92 - `python3 -m pip install --upgrade "skillevaluator[all]"` inside an active93 virtual environment94 - with no install, prefix each command with `uvx --python 3.13 --from "skillevaluator[all]"`9596 Ask the user before installing into a system or shared Python; never use97 `sudo pip`. If the binary is installed but not on `PATH`, run98 `uv tool update-shell` or add `~/.local/bin` to `PATH`. If a documented99 command or flag is unknown, upgrade: `uv tool upgrade skillevaluator`. If100 installation fails (no network, no Python 3.12+), stop and report the101 exact error and the install command instead of guessing results.1022. **Locate the target.** Confirm the path has `SKILL.md` and that its103 frontmatter `name` matches the directory name. For a folder of skills, the104 commands evaluate each skill inside it.1053. **Check readiness before paid runs.** Run `skillevaluator health-check --tier 1`106 for scanners, `skillevaluator doctor --tier 2` for providers, and107 `skillevaluator doctor --env-mode docker` (add `--verify-models`) for Tier 3.108 Fix every failing row first.1094. **Start keyless.** Run `skillevaluator tier1 <skill-dir> --no-llm`. Fix110 CRITICAL and HIGH findings before anything else; `lint` findings are advisory.1115. **Add LLM checks** when a provider is set: `skillevaluator tier1 <skill-dir>`112 (rubric, LLM security, verification) and `skillevaluator tier2 <skill-dir>`.1136. **Prepare Tier 3 cases.** If `<skill-dir>/evals/evals.json` is missing, first114 capture task requests and observable outcomes in `<skill-dir>/evals/EVAL.md`;115 headings alone do not qualify. Generate with116 `skillevaluator create-eval-dataset <skill-dir> --full --prompt <skill-dir>/evals/EVAL.md`,117 then review it. The default prefers author guidance, then matching retained118 traces; existing datasets need `--force` or `--refine`. Skill-only119 generation requires explicit opt-in with `--grounding skill`. Review:120 positive cases (explicit, implicit, contextual) and at least one negative121 case with `"expected_skill": null`. Required shape: top-level `skill_name`122 and an `evals` array; each case has `id`, `prompt`, `expected_output`, and123 `expected_skill` (optional `assertions`, `files`). Validate with124 `skillevaluator tier3 validate <skill-dir> --strict`. Format:125 [references/tier3-datasets.md](references/tier3-datasets.md); run policy and126 scoring: [references/tier3-running.md](references/tier3-running.md).1277. **Run live evaluation.** `skillevaluator tier3 <skill-dir>` (or128 `skillevaluator tier3 evaluate <skill-dir> -a opencode --env-mode docker --n-attempts 3`).129 Use `--max-cases 1` for a cheap smoke run first; such runs are never130 publication evidence.1318. **Read the results** (see below), open `skillevaluator view <skill-dir>`, and132 for follow-up questions run `skillevaluator tier3 feedback <run-dir>`.1339. **Iterate.** Change the skill, rerun the same command with the same cases,134 agent and model, and compare. Treat a single run's lift as directional.135136## Read The Results137138Exit codes: `0` success, `1` a gate failed, evidence is `INCOMPLETE`, or the139run could not complete, `2` usage error (bad flag or missing path; fix the140command, not the skill).141142- **Quality** (0-100): Correctness 35%, Discoverability 25%, Reliability 25%,143 Efficiency 15%. Grades A>=90, B>=80, C>=70. Passing needs `--min-score`144 (default 70) and no HIGH/CRITICAL quality finding.145- **Rubric** (0-100): nine criteria scored 0-10; passing needs the weighted146 score >= `--min-score` and every criterion >= 7.147- **Tier 2**: HIGH or CRITICAL duplicate findings exit `1` in `tier2 PATH`.148- **Tier 3**: five dimensions (Security, Correctness, Discoverability,149 Effectiveness, Efficiency), each PASS >= 0.50, NEUTRAL 0.40-0.50, FAIL < 0.40.150 Verdict PASS needs every dimension >= 0.50 for at least one agent. Skill151 Lift = with-skill overall - baseline overall; PASS >= +0.05. `INCONCLUSIVE:152 skill never activated` means no positive trial loaded the skill; fix the153 description or prompts, not the scores. `tier3 PATH` exits `0` on a `FAIL`154 verdict; only an incomplete run exits `1`.155- **Missing scores are `NO SCORE` or `None`, never 0.** Do not average them in.156- **Publication**: require `publication_status == "pass"` in the JSON report,157 not just `overall_passed`.158159Report anatomy and JSON fields: [references/reports-and-ci.md](references/reports-and-ci.md).160161## Examples162163```bash164# Keyless first look165skillevaluator quality-check <skill-dir> -r cli -r json -o <report-dir>166167# Static gate for a whole collection, complete report even on failures168skillevaluator validate <skills-dir> --profile default --tiers 1 -c -r json,markdown -o reports169170# LLM-backed Tier 1 and Tier 2, dedup advisory171skillevaluator validate <skill-dir> --tiers 1,2 --llm --no-block-on-dedup172173# Live A/B evaluation with two agents, retaining trajectories for debugging174skillevaluator tier3 evaluate <skill-dir> -a opencode,codex --n-attempts 3 --harbor-keep-jobs175176# Baseline only, to calibrate cases before the skill exists177skillevaluator tier3 evaluate <skill-dir> --skip-with-skill178```179180## Limitations181182- Tier 1 and the quality score are static: they check structure and wording,183 not whether the skill works. Only Tier 3 observes agent behavior.184- LLM judges (rubric, Tier 3 correctness/effectiveness) vary between runs and185 models; compare runs only with the same model, cases, and attempts.186- Tier 3 costs model tokens and sandbox time per case x attempt x agent x 2187 arms; a generated starter case gives limited coverage.188- `validate --tiers` always includes Tier 1; `--tiers 2` or `--tiers 3` alone is189 rejected. Use `tier2 PATH` or `tier3 PATH` to run a tier on its own.190- Agent credentials come only from the host environment; `<skill-dir>/evals/config.yml`191 `runtime_env` rejects provider keys.192193## Troubleshooting194195| Symptom | Cause | Fix |196| --- | --- | --- |197| `skillevaluator: command not found` | CLI not installed or not on `PATH` | Workflow step 1: install with `uv tool install`, `pipx`, or `pip` in a virtual environment, or use `uvx` |198| Exit `2` | Unknown flag, bad value, or missing path | Check `skillevaluator <command> --help`; prefix paths named like commands with `./` |199| Check shows `INCOMPLETE` | A scanner is missing or failed | Run `skillevaluator health-check --tier 1`; install the `security` extra or the missing scanner |200| "provider is required" / exit `1` before reports | No `SKILL_EVAL_LLM_PROVIDER` or key, or several keys exported | Set exactly one provider and its key; see providers reference |201| Quality below 70 | Missing `## Prerequisites`, `## Limitations`, `## Troubleshooting`, vague description, no examples | Read each finding's suggestion; do not stuff keywords |202| `INCONCLUSIVE: skill never activated` | Description does not match the prompts | Make the description name the tasks; add explicit-bucket cases |203| Docker trials fail to start | Daemon down or outdated engine | `docker info`; rerun `skillevaluator doctor --env-mode docker` |204| Agent model rejected | Default model not valid for that agent | `--agent-model AGENT=MODEL`, verify with `doctor --verify-models` |205| Run incomplete (`Scored attempt coverage is n/m`) | A trial errored or timed out | Rerun; raise `--timeout-multiplier`; inspect with `--harbor-keep-jobs` |206207More cases: [references/troubleshooting.md](references/troubleshooting.md).208209## Final Response210211Report to the user:212213- the exact commands run and their exit codes214- scores and verdicts per tier, quoting the report values (not estimates)215- the top findings to fix, each with its file and suggested change216- report paths (`<report-dir>/...`, `<skill-dir>/evals/results/<run-id>/report.html`)217- what was not run (skipped tiers, missing keys, `--max-cases` smoke runs) and218 therefore not proven