
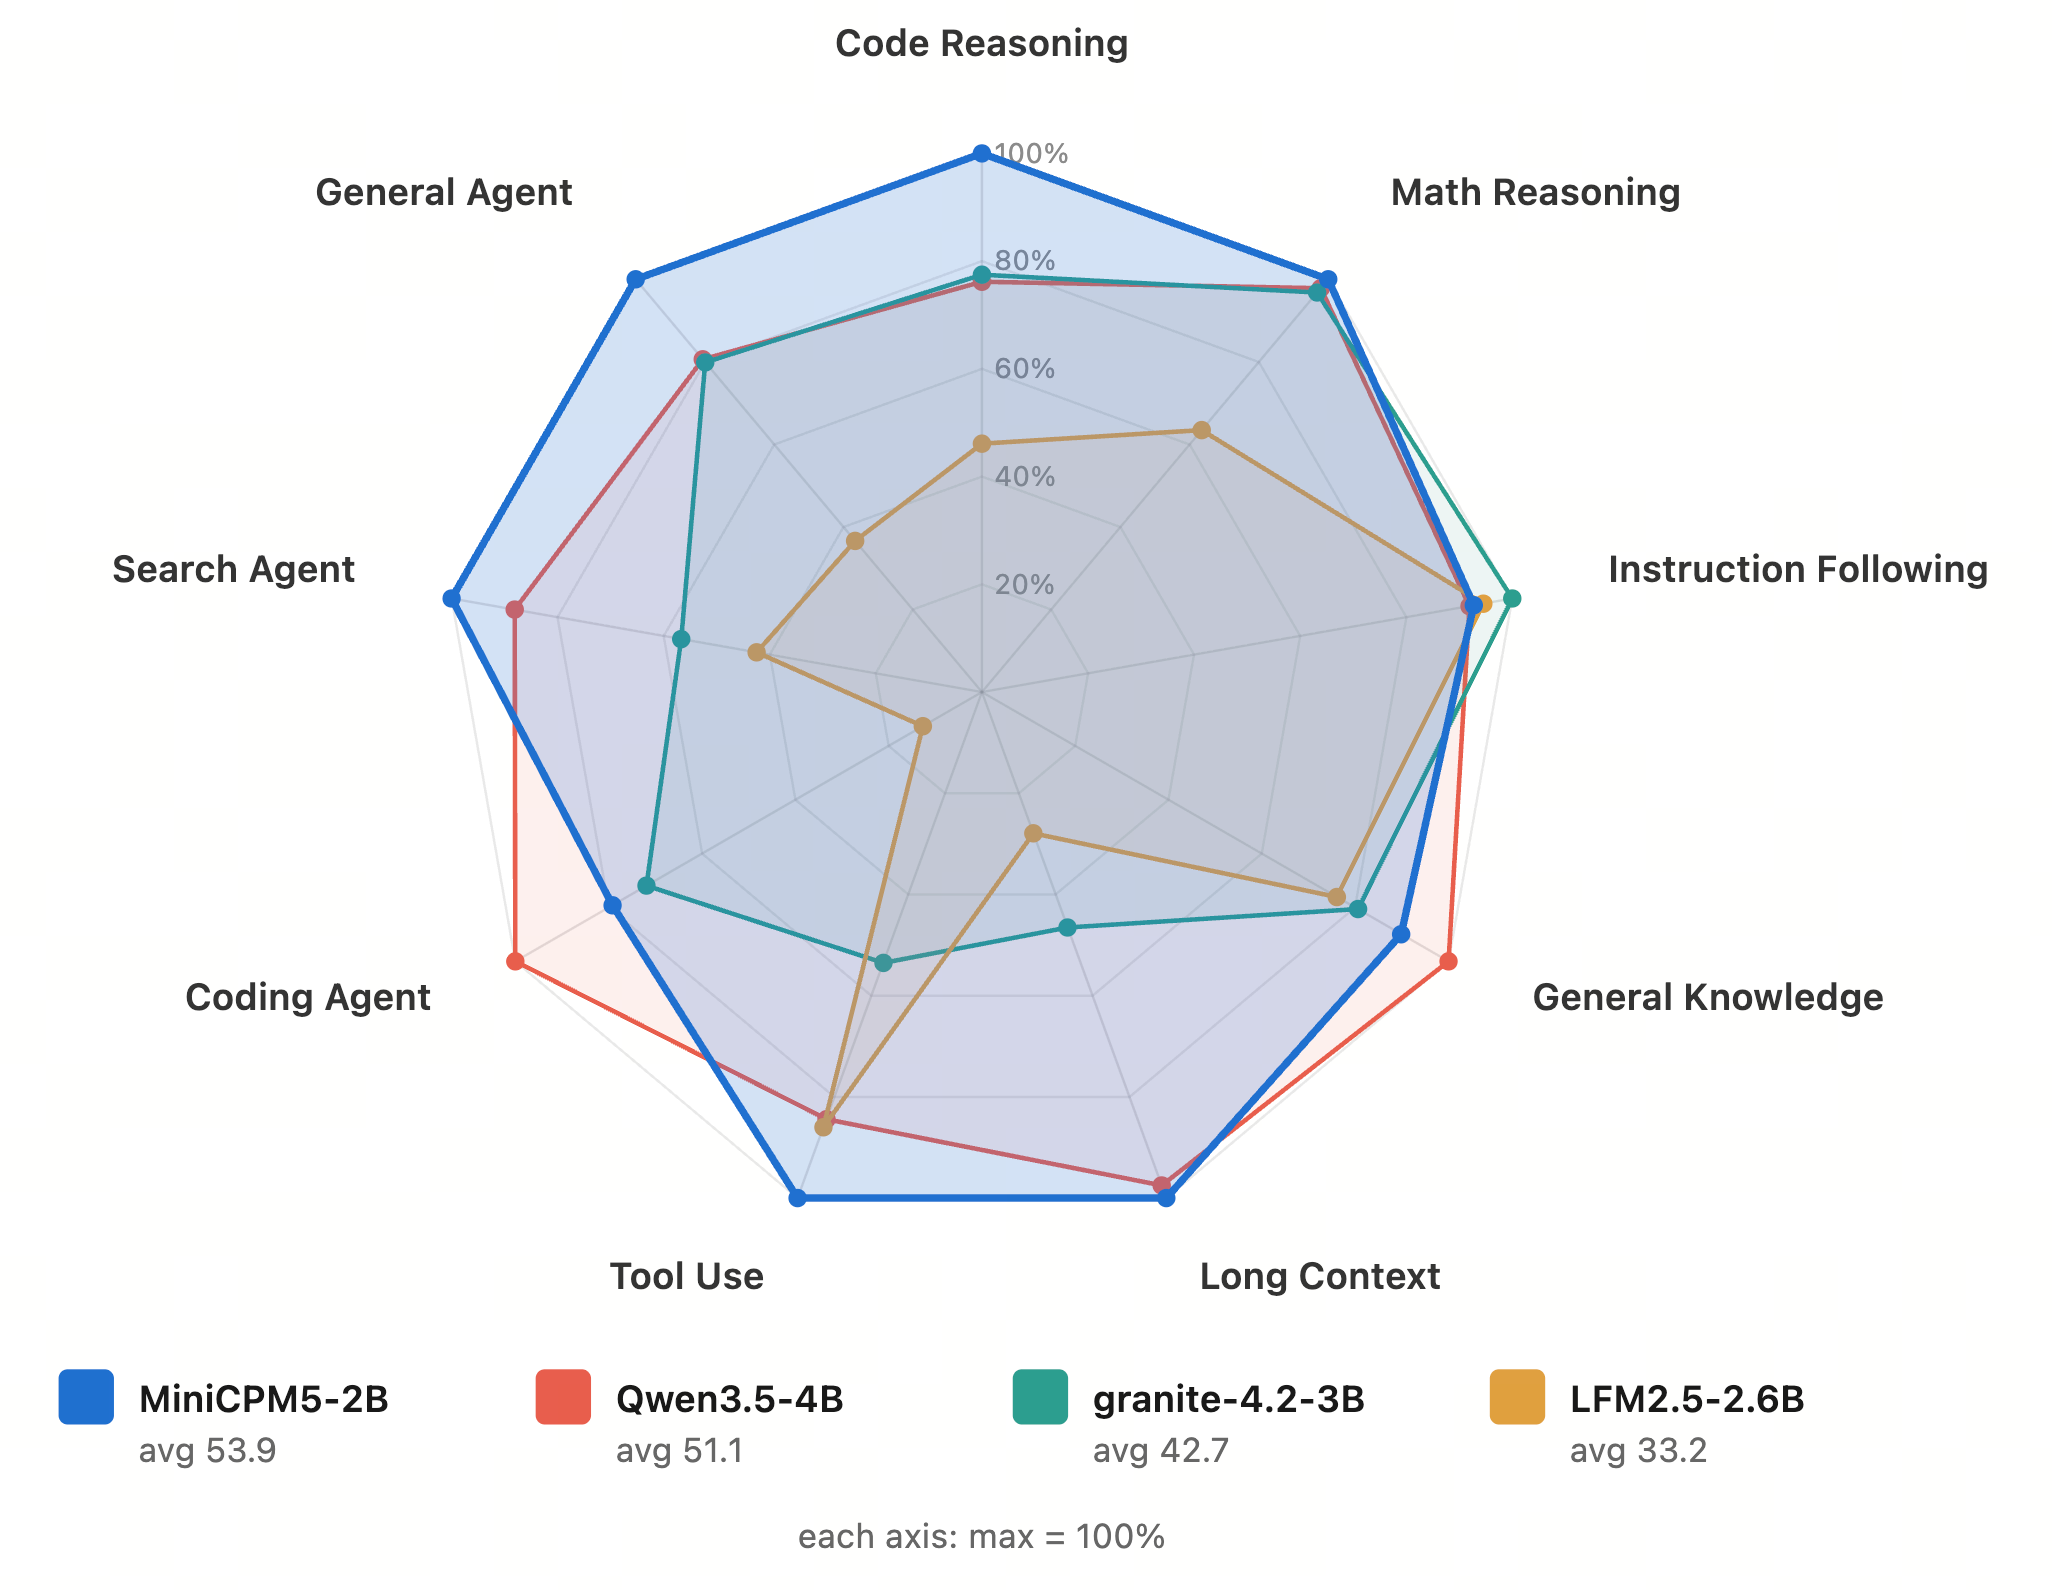
Deploy MiniCPM5-1B and MiniCPM5-2B with llama.cpp
CPU / edge / consumer-GPU deployment via the released GGUF artifacts. The artifacts work directly with vanilla llama.cpp and every downstream runtime (Ollama / LM Studio / llama-cpp-python).
Required input
| Var | Example | Default |
|---|---|---|
GGUF_REPO |
openbmb/MiniCPM5-2B-GGUF |
required; openbmb/MiniCPM5-1B-GGUF also works |
QUANT |
Q4_K_M (1.56 GB, recommended) / Q8_0 (2.68 GB) / F16 (5.04 GB) |
Q4_K_M |
NGL |
99 (all layers on GPU) / 0 (CPU only) |
99 if NVIDIA GPU, else 0 |
CTX |
8192 (default) up to 131072 (128 K) |
8192 |
Steps
1. Install llama.cpp
# macOS
brew install llama.cpp

# Linux / cross-platform: pre-built binary
curl -fsSL https://github.com/ggerganov/llama.cpp/releases/latest/download/llama-cli-linux.tar.gz | tar -xz
# OR build from source:
git clone --depth=1 https://github.com/ggerganov/llama.cpp.git && cd llama.cpp
mkdir build && cd build
cmake .. -DGGML_CUDA=ON -DCMAKE_BUILD_TYPE=Release    # CPU-only: omit GGML_CUDA=ON
cmake --build . --config Release -j $(nproc) --target llama-cli llama-server
2. Download the GGUF
mkdir -p ~/minicpm5 && cd ~/minicpm5
huggingface-cli download ${GGUF_REPO} MiniCPM5-2B-${QUANT}.gguf --local-dir .
3a. Interactive chat (CLI)
llama-cli -m MiniCPM5-2B-${QUANT}.gguf \
    -n 2048 --temp 1.0 --top-p 0.95 -ngl ${NGL} -c ${CTX}
3b. OpenAI-compatible HTTP server
llama-server -m MiniCPM5-2B-${QUANT}.gguf \
    --port 8080 -ngl ${NGL} -c ${CTX} --jinja
4. Validate
curl http://localhost:8080/v1/chat/completions \
    -H "Content-Type: application/json" \
    -d '{
        "model": "MiniCPM5-2B",
        "messages": [{"role":"user","content":"1+1=?"}],
        "temperature": 1.0, "top_p": 0.95, "max_tokens": 64
    }'
Expected: "2" in the reply.
Sampling defaults
| Mode | --temp |
--top-p |
|---|---|---|
| MiniCPM5-2B Think | 1.0 | 0.95 |
| MiniCPM5-1B Think | 0.9 | 0.95 |
| MiniCPM5-1B No-think | 0.7 | 0.95 |
Choosing a quant
| Quant | Disk | Quality |
|---|---|---|
| F16 | 5.04 GB | reference |
| Q8_0 | 2.68 GB | ~indistinguishable from F16 |
| Q4_K_M | 1.56 GB | small drop, ideal for laptops |
Common pitfalls
- Slow on CPU + large context: drop
-c 131072to-c 8192if you don't need 128 K.
Building your own GGUF (advanced)
If you've trained your own MiniCPM5-1B or MiniCPM5-2B variant, build a GGUF with:
python convert_hf_to_gguf.py /path/to/your-fp16-hf --outfile out/F16.gguf --outtype f16
llama-quantize out/F16.gguf out/Q4_K_M.gguf Q4_K_M
Trained a LoRA adapter (not a full model) and want to apply it at runtime with --lora instead of baking it in? Convert it to a GGUF adapter — see minicpm5-finetune-gguf-lora.
When NOT to use
- NVIDIA GPU + want OpenAI-compatible serving →
minicpm5-deploy-vllm - Apple Silicon native →
minicpm5-deploy-mlxis faster - Just want one-line desktop run →
minicpm5-deploy-ollama - Want a desktop GUI →
minicpm5-deploy-lmstudio