roast-my-code
Roast the target codebase with devastating accuracy and actionable fixes.
Usage
/roast                              # Review cwd at spicy level
/roast src/                         # Review src/ directory
/roast --level=savage               # Maximum roast intensity
/roast src/ --level=sensei          # TDD-focused wisdom
/roast --diff                       # Review staged changes only
/roast --quick                      # Fast scan (top 3 checkers)
/roast --lang=ja                    # Force output language
Levels
| Level |
Tone |
Best For |
| gentle |
Friendly mentor |
Juniors, OSS contributors |
| spicy |
Sarcastic reviewer (default) |
Daily use, team reviews |
| savage |
Brutally honest senior |
Content, self-roasts |
| sensei |
TDD master (t_wada style) |
TDD adoption, testing culture |
Instructions
Follow these steps precisely. Do NOT skip any step.
Step 1: Parse Arguments
Parse the user's input to extract:
TARGET_PATH: directory or file to review (default: current working directory)LEVEL: one of gentle/spicy/savage/sensei (default: spicy)OUTPUT_LANG: detect from the user's message language (en or ja).
If the user wrote in Japanese, set to ja. Otherwise, set to en.
If --lang= is specified, use that value instead of auto-detection.DIFF_MODE: boolean (default: false). If --diff is present, set to true.QUICK_MODE: boolean (default: false). If --quick is present, set to true.
Extract --level=, --lang=, --diff, --quick from the argument string.
Everything else is treated as the target path.
Diff mode: When DIFF_MODE is true, run git diff --cached --name-only
via Bash to get the list of staged files. Only analyze those files instead
of the full project. If no files are staged, inform the user and exit.
Project detection (Step 2) still runs normally to determine framework context.
Quick mode: When QUICK_MODE is true, run only these 3 checkers:
Security, Architecture, TDD. Skip all other checkers. Output includes a
note that this was a quick scan.
Step 2: Project Detection
Analyze the target to detect the project type. Run these checks:
Glob: TARGET_PATH/**/package.json
Glob: TARGET_PATH/**/tsconfig.json
Glob: TARGET_PATH/**/Cargo.toml
Glob: TARGET_PATH/**/go.mod
Glob: TARGET_PATH/**/requirements.txt
Glob: TARGET_PATH/**/pyproject.toml
Glob: TARGET_PATH/**/*.sln
Glob: TARGET_PATH/.git
Read the root-level package.json (at TARGET_PATH/package.json) first.
If none exists, fall back to the nearest package.json to TARGET_PATH.
Extract:
dependencies and devDependencies keysscripts keysengines field
Detect frameworks by checking dependency names:
- HTTP frameworks: express, hono, fastify, koa, @nestjs/core
- Frontend frameworks: react, vue, svelte, @angular/core, next, nuxt
- Test frameworks: jest, vitest, mocha, @testing-library/*
- Language: presence of tsconfig.json = TypeScript
Store results as:
LANG: typescript | javascript | rust | go | python | csharp | unknownHAS_TESTS: booleanHAS_HTTP_FRAMEWORK: booleanHAS_FRONTEND_FRAMEWORK: booleanHAS_GIT: booleanHAS_PACKAGE_MANIFEST: boolean
Step 3: Checker Activation
Determine which checkers to run based on detection results:
| Checker |
Reference File |
Condition |
| Security |
references/security.md |
Always |
| Architecture |
references/architecture.md |
Always |
| Complexity |
references/complexity.md |
Always |
| TDD |
references/tdd.md |
Always |
| Type Safety |
references/type-safety.md |
LANG = typescript OR .ts/.tsx files found |
| Error Handling |
references/error-handling.md |
Always |
| Naming |
references/naming.md |
Always |
| Dead Code |
references/dead-code.md |
Always |
| Performance |
references/performance.md |
Always |
| Dependencies |
references/dependencies.md |
HAS_PACKAGE_MANIFEST |
| API Design |
references/api-design.md |
HAS_HTTP_FRAMEWORK |
| Frontend |
references/frontend.md |
HAS_FRONTEND_FRAMEWORK |
| Git Hygiene |
references/git-hygiene.md |
HAS_GIT |
Step 4: Execute Checks (2-Phase)
Uses a compact index for fast detection, then reads full reference files
only for categories with findings.
Phase 1: Quick Scan
Read references/checks-index.md (single file — all 162 check
patterns in one place).
Batch Grep execution — combine patterns per category x severity:
- For each active checker category, combine all Grep patterns at the
same severity level using
| (OR) into a single Grep call.
- Example: Security Grep [critical] has 6 patterns — combine into
1 Grep call with patterns joined by
|.
- This reduces ~100+ individual Greps to ~20-30 batched calls.
- Presence (P): pattern found = potential finding. Map matched
lines back to the specific check by inspecting which sub-pattern
matched.
- Absence (A): run a separate Grep per absence check. Zero
results = finding.
Glob checks — run all Glob patterns from the index in parallel.
Bash checks — run Bash commands from the index in parallel where
independent. Group related commands together.
Map results — for each match, identify the specific check name
from the index. Record:
- Which categories have findings (= need Phase 2 detail)
- Which categories are clean (= Strengths, skip in Phase 2)
- Approximate severity distribution per category
Phase 1 rules:
- Skip
node_modules/, dist/, build/, .next/, vendor/,
target/, .git/ directories.
- Sample up to 20 files per category for tractability.
- For large projects, prioritize:
src/ > lib/ > app/ > others.
Phase 1 target: ~20-30 Grep + 10-15 Glob/Bash calls total.
Phase 2: Detailed Roast
Read references/roast-style.md to load the roast persona for
the selected LEVEL.
For each category WITH findings from Phase 1:
a. Read the category's full reference file (e.g.,
references/security.md).
b. For each finding detected in Phase 1, extract from the reference:
- Roast line (en and ja — select based on OUTPUT_LANG)
- Fix description
- Exact deduction value
c. Refine findings: verify context around matches, discard false
positives from batch grep, deepen analysis where needed.
d. Record each confirmed finding with:
category: checker namecheck: check item nameseverity: critical / error / warning / infolocation: file path and line number(s)evidence: the actual code/pattern founddeduction: point deduction value
For categories with zero findings: do NOT read the reference
file. Add the category to Strengths in the final output.
Important rules:
- Only report findings backed by actual evidence found in the code.
- Do NOT invent findings for entertainment. Every roast must be
grounded in fact.
- Deduplication: If the same issue appears in multiple checkers
(e.g., CORS in Security and API Design, Error Boundaries in Error
Handling and Frontend), count the deduction in only ONE category —
whichever is more specific. Note the cross-reference in the other
category without deducting.
- Per-check cap: max 3 findings per check type count toward the
score. Additional instances are reported but do not deduct further.
- Parallelism: Run Grep and Glob calls for independent checks in
parallel where possible. Batch tool calls to minimize round-trips.
Step 5: Calculate Scores
For each active checker category:
- Start at 100 points.
- Apply deductions for each finding:
critical: -20 pointserror: -10 pointswarning: -4 pointsinfo: -1 point
- Per-check cap: Max 3 findings per check type count toward the
score. Additional instances are reported but do not deduct further points.
- Floor at 0 (no negative scores).
- The category score displayed in the table is always out of 100
(do NOT multiply by weight here).
Calculate the Overall Score using category weights:
- Weights: Security 1.5x, Architecture 1.2x,
TDD 1.5x in sensei mode (1.0x otherwise), all others 1.0x.
overall = sum(score_i * weight_i) / sum(weight_i)- Weights are used ONLY in this overall calculation, not on individual
category scores.
Determine the Grade:
| Grade |
Score Range |
Label |
| S |
90 - 100 |
Immaculate |
| A |
80 - 89 |
Solid |
| B |
70 - 79 |
Decent |
| C |
60 - 69 |
Needs Work |
| D |
40 - 59 |
Rough |
| F |
0 - 39 |
Dumpster Fire |
Step 6: Generate Output
Compose the final output using the Output Format below.
Apply the roast persona from roast-style.md for the selected LEVEL.
Rules:
- Every finding gets a roast line AND a concrete fix.
- Group findings by category.
- Show the most critical findings first within each category.
- Keep total output under 300 lines. If more findings exist, show top 5 per
category and note how many were omitted.
- Lines should be under 80 characters where possible for screenshot-friendliness.
- Language: If
OUTPUT_LANG is ja, write all roast lines, fix descriptions,
summary text, and section labels in Japanese. Category names in the scorecard
table and structural elements (box-drawing, header) remain in English.
If OUTPUT_LANG is en, write everything in English.
Output Format
Generate output following this structure (adapt rows to active checkers):
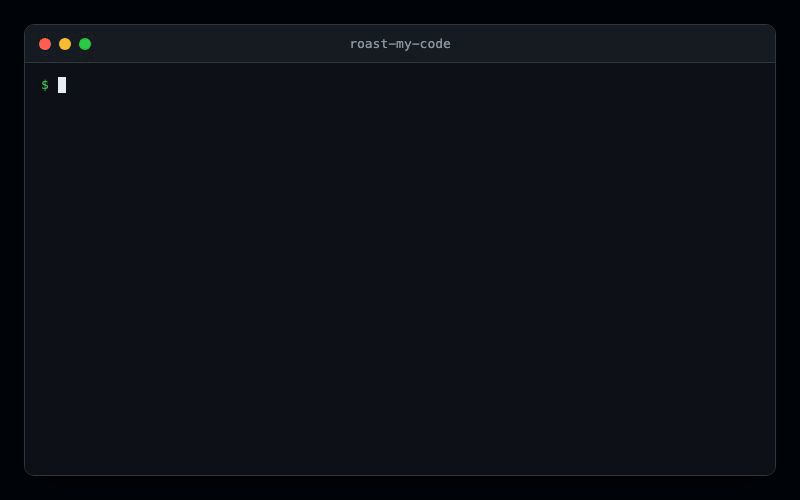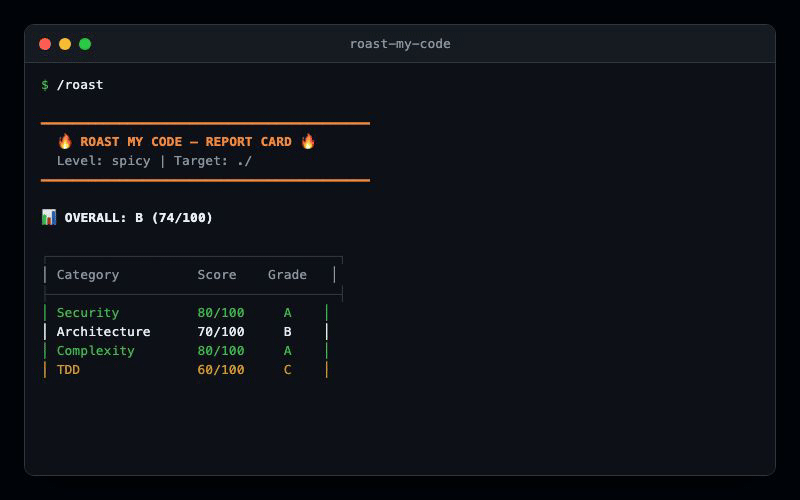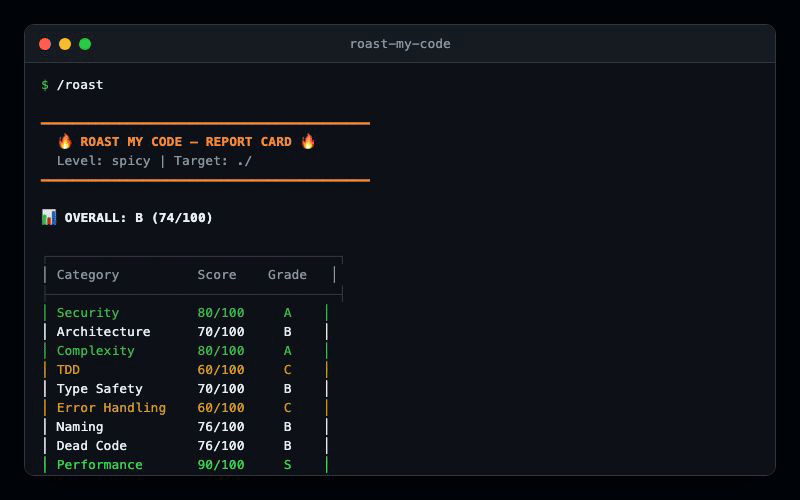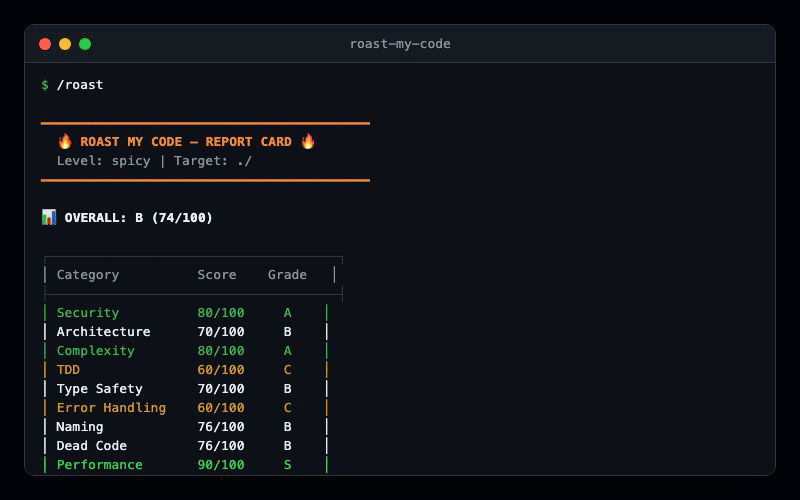
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
  🔥 ROAST MY CODE — REPORT CARD 🔥
  Level: {LEVEL} | Target: {TARGET_PATH}
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━

📊 OVERALL: {GRADE} ({SCORE}/100)

┌─────────────────────────────────────┐
│ Category          Score    Grade    │
├─────────────────────────────────────┤
│ Security          {xx}/100   {G}   │
│ Architecture      {xx}/100   {G}   │
│ Complexity        {xx}/100   {G}   │
│ TDD               {xx}/100   {G}   │
│ Type Safety       {xx}/100   {G}   │
│ Error Handling    {xx}/100   {G}   │
│ Naming            {xx}/100   {G}   │
│ Dead Code         {xx}/100   {G}   │
│ Performance       {xx}/100   {G}   │
│ Dependencies      {xx}/100   {G}   │
│ API Design        {xx}/100   {G}   │
│ Frontend          {xx}/100   {G}   │
│ Git Hygiene       {xx}/100   {G}   │
└─────────────────────────────────────┘
(Only show rows for active checkers)

━━━ 🔥 FINDINGS ━━━━━━━━━━━━━━━━━━━━━━

## {CATEGORY} ({SCORE}/100)

### 🚨 {CHECK_NAME} [{SEVERITY}]
📍 {file_path}:{line}
> {code evidence or description}

💬 "{ROAST_LINE}"

🔧 Fix: {actionable fix description}

---

(Repeat for each finding, grouped by category)

━━━ 📋 SUMMARY ━━━━━━━━━━━━━━━━━━━━━━━

🏆 Top 3 Strengths:
  1. {strength}
  2. {strength}
  3. {strength}

💀 Top 3 Priorities to Fix:
  1. {priority with file reference}
  2. {priority with file reference}
  3. {priority with file reference}

📈 Quick Wins (< 5 min each):
  - {quick fix 1}
  - {quick fix 2}
  - {quick fix 3}

━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
  Roasted with ❤️ by roast-my-code
  ⭐ github.com/sakimyto/roast-my-code
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
Output Rules
- Scorecard table always appears first.
- Findings are grouped by category, ordered by score
(worst category first).
- Within each category, findings are ordered: critical > error >
warning > info.
- Summary always appears last.
- If a category scored 100 (no findings), show it in the table
but skip the findings section for it. Add it to Strengths.
- The roast line MUST match the selected LEVEL's tone from
roast-style.md.
- Every roast MUST be paired with a Fix.
- Use box-drawing characters for the table exactly as shown.
- If the overall grade is S, add a congratulatory roast:
"I came here to roast, but your code left me speechless.
Well played."
Scoring Quick Reference
| Severity |
Deduction |
Examples |
| critical |
-20 |
Hardcoded secrets, SQL injection, no tests |
| error |
-10 |
Empty catch, God files, any abuse |
| warning |
-4 |
console.log, TODO comments, inline styles |
| info |
-1 |
Missing engine field, no readonly |
| Weight |
Category |
Multiplier |
Note |
| High |
Security |
1.5x |
Always |
| Medium |
Architecture |
1.2x |
Always |
| Elevated |
TDD |
1.5x |
sensei mode only (1.0x otherwise) |
| Normal |
All others |
1.0x |
|
Note: Weights apply ONLY to the overall weighted average, not to
individual category scores (which are always displayed out of 100).
Per-check cap: max 3 findings per check type count toward the score.
| Grade |
Range |
Vibe |
| S |
90-100 |
Ship it yesterday |
| A |
80-89 |
Production-ready |
| B |
70-79 |
Code review approved |
| C |
60-69 |
Needs another pass |
| D |
40-59 |
Intern's first week? |
| F |
0-39 |
Call the fire department |
1---2name: roast-my-code3description: "Comprehensive code review in roast style. Analyzes security, architecture, complexity, TDD compliance, type safety, error handling, naming, dead code, performance, dependencies, API design, frontend quality, and git hygiene. Delivers findings as entertaining roasts with actionable fixes. Use /roast to review your codebase. Supports --level (gentle/spicy/savage/sensei)."4user-invocable: true5argument-hint: "[target-path] [--level=gentle|spicy|savage|sensei] [--diff] [--quick] [--lang=en|ja]"6allowed-tools: Read, Glob, Grep, Bash7metadata:8 source: https://skillmd.com/skills/sakimyto/roast-my-code9---1011# roast-my-code1213Roast the target codebase with devastating accuracy and actionable fixes.1415## Usage1617```18/roast # Review cwd at spicy level19/roast src/ # Review src/ directory20/roast --level=savage # Maximum roast intensity21/roast src/ --level=sensei # TDD-focused wisdom22/roast --diff # Review staged changes only23/roast --quick # Fast scan (top 3 checkers)24/roast --lang=ja # Force output language25```2627## Levels2829| Level | Tone | Best For |30|-------|------|----------|31| gentle | Friendly mentor | Juniors, OSS contributors |32| **spicy** | Sarcastic reviewer (default) | Daily use, team reviews |33| savage | Brutally honest senior | Content, self-roasts |34| sensei | TDD master (t_wada style) | TDD adoption, testing culture |3536## Instructions3738Follow these steps precisely. Do NOT skip any step.3940### Step 1: Parse Arguments4142Parse the user's input to extract:4344- `TARGET_PATH`: directory or file to review (default: current working directory)45- `LEVEL`: one of gentle/spicy/savage/sensei (default: spicy)46- `OUTPUT_LANG`: detect from the user's message language (en or ja).47 If the user wrote in Japanese, set to ja. Otherwise, set to en.48 If `--lang=` is specified, use that value instead of auto-detection.49- `DIFF_MODE`: boolean (default: false). If `--diff` is present, set to true.50- `QUICK_MODE`: boolean (default: false). If `--quick` is present, set to true.5152Extract `--level=`, `--lang=`, `--diff`, `--quick` from the argument string.53Everything else is treated as the target path.5455**Diff mode:** When `DIFF_MODE` is true, run `git diff --cached --name-only`56via Bash to get the list of staged files. Only analyze those files instead57of the full project. If no files are staged, inform the user and exit.58Project detection (Step 2) still runs normally to determine framework context.5960**Quick mode:** When `QUICK_MODE` is true, run only these 3 checkers:61Security, Architecture, TDD. Skip all other checkers. Output includes a62note that this was a quick scan.6364### Step 2: Project Detection6566Analyze the target to detect the project type. Run these checks:6768```69Glob: TARGET_PATH/**/package.json70Glob: TARGET_PATH/**/tsconfig.json71Glob: TARGET_PATH/**/Cargo.toml72Glob: TARGET_PATH/**/go.mod73Glob: TARGET_PATH/**/requirements.txt74Glob: TARGET_PATH/**/pyproject.toml75Glob: TARGET_PATH/**/*.sln76Glob: TARGET_PATH/.git77```7879Read the **root-level** `package.json` (at `TARGET_PATH/package.json`) first.80If none exists, fall back to the nearest `package.json` to TARGET_PATH.81Extract:8283- `dependencies` and `devDependencies` keys84- `scripts` keys85- `engines` field8687Detect frameworks by checking dependency names:8889- **HTTP frameworks:** express, hono, fastify, koa, @nestjs/core90- **Frontend frameworks:** react, vue, svelte, @angular/core, next, nuxt91- **Test frameworks:** jest, vitest, mocha, @testing-library/*92- **Language:** presence of tsconfig.json = TypeScript9394Store results as:9596- `LANG`: typescript | javascript | rust | go | python | csharp | unknown97- `HAS_TESTS`: boolean98- `HAS_HTTP_FRAMEWORK`: boolean99- `HAS_FRONTEND_FRAMEWORK`: boolean100- `HAS_GIT`: boolean101- `HAS_PACKAGE_MANIFEST`: boolean102103### Step 3: Checker Activation104105Determine which checkers to run based on detection results:106107| Checker | Reference File | Condition |108|---------|---------------|-----------|109| Security | `references/security.md` | Always |110| Architecture | `references/architecture.md` | Always |111| Complexity | `references/complexity.md` | Always |112| TDD | `references/tdd.md` | Always |113| Type Safety | `references/type-safety.md` | LANG = typescript OR .ts/.tsx files found |114| Error Handling | `references/error-handling.md` | Always |115| Naming | `references/naming.md` | Always |116| Dead Code | `references/dead-code.md` | Always |117| Performance | `references/performance.md` | Always |118| Dependencies | `references/dependencies.md` | HAS_PACKAGE_MANIFEST |119| API Design | `references/api-design.md` | HAS_HTTP_FRAMEWORK |120| Frontend | `references/frontend.md` | HAS_FRONTEND_FRAMEWORK |121| Git Hygiene | `references/git-hygiene.md` | HAS_GIT |122123### Step 4: Execute Checks (2-Phase)124125Uses a compact index for fast detection, then reads full reference files126only for categories with findings.127128#### Phase 1: Quick Scan1291301. **Read** `references/checks-index.md` (single file — all 162 check131 patterns in one place).1321332. **Batch Grep execution** — combine patterns per category x severity:134 - For each active checker category, combine all Grep patterns at the135 same severity level using `|` (OR) into a single Grep call.136 - Example: Security Grep [critical] has 6 patterns — combine into137 1 Grep call with patterns joined by `|`.138 - This reduces ~100+ individual Greps to ~20-30 batched calls.139 - **Presence (P)**: pattern found = potential finding. Map matched140 lines back to the specific check by inspecting which sub-pattern141 matched.142 - **Absence (A)**: run a separate Grep per absence check. Zero143 results = finding.1441453. **Glob checks** — run all Glob patterns from the index in parallel.1461474. **Bash checks** — run Bash commands from the index in parallel where148 independent. Group related commands together.1491505. **Map results** — for each match, identify the specific check name151 from the index. Record:152 - Which categories have findings (= need Phase 2 detail)153 - Which categories are clean (= Strengths, skip in Phase 2)154 - Approximate severity distribution per category155156**Phase 1 rules:**157158- Skip `node_modules/`, `dist/`, `build/`, `.next/`, `vendor/`,159 `target/`, `.git/` directories.160- Sample up to 20 files per category for tractability.161- For large projects, prioritize: `src/` > `lib/` > `app/` > others.162163**Phase 1 target: ~20-30 Grep + 10-15 Glob/Bash calls total.**164165#### Phase 2: Detailed Roast1661671. **Read** `references/roast-style.md` to load the roast persona for168 the selected LEVEL.1691702. **For each category WITH findings** from Phase 1:171 a. Read the category's full reference file (e.g.,172 `references/security.md`).173 b. For each finding detected in Phase 1, extract from the reference:174 - Roast line (en and ja — select based on OUTPUT_LANG)175 - Fix description176 - Exact deduction value177 c. Refine findings: verify context around matches, discard false178 positives from batch grep, deepen analysis where needed.179 d. Record each confirmed finding with:180 - `category`: checker name181 - `check`: check item name182 - `severity`: critical / error / warning / info183 - `location`: file path and line number(s)184 - `evidence`: the actual code/pattern found185 - `deduction`: point deduction value1861873. **For categories with zero findings**: do NOT read the reference188 file. Add the category to Strengths in the final output.189190**Important rules:**191192- Only report findings backed by actual evidence found in the code.193- Do NOT invent findings for entertainment. Every roast must be194 grounded in fact.195- **Deduplication:** If the same issue appears in multiple checkers196 (e.g., CORS in Security and API Design, Error Boundaries in Error197 Handling and Frontend), count the deduction in only ONE category —198 whichever is more specific. Note the cross-reference in the other199 category without deducting.200- Per-check cap: max **3 findings** per check type count toward the201 score. Additional instances are reported but do not deduct further.202- **Parallelism:** Run Grep and Glob calls for independent checks in203 parallel where possible. Batch tool calls to minimize round-trips.204205### Step 5: Calculate Scores206207For each active checker category:2082091. Start at **100 points**.2102. Apply deductions for each finding:211 - `critical`: **-20** points212 - `error`: **-10** points213 - `warning`: **-4** points214 - `info`: **-1** point2153. **Per-check cap:** Max **3 findings** per check type count toward the216 score. Additional instances are reported but do not deduct further points.2174. Floor at **0** (no negative scores).2185. The category score displayed in the table is always out of **100**219 (do NOT multiply by weight here).220221Calculate the **Overall Score** using category weights:222223- Weights: Security **1.5x**, Architecture **1.2x**,224 TDD **1.5x** in sensei mode (1.0x otherwise), all others **1.0x**.225- `overall = sum(score_i * weight_i) / sum(weight_i)`226- Weights are used ONLY in this overall calculation, not on individual227 category scores.228229Determine the **Grade**:230231| Grade | Score Range | Label |232|-------|-----------|-------|233| S | 90 - 100 | Immaculate |234| A | 80 - 89 | Solid |235| B | 70 - 79 | Decent |236| C | 60 - 69 | Needs Work |237| D | 40 - 59 | Rough |238| F | 0 - 39 | Dumpster Fire |239240### Step 6: Generate Output241242Compose the final output using the Output Format below.243Apply the roast persona from roast-style.md for the selected LEVEL.244245**Rules:**246247- Every finding gets a roast line AND a concrete fix.248- Group findings by category.249- Show the most critical findings first within each category.250- Keep total output under 300 lines. If more findings exist, show top 5 per251 category and note how many were omitted.252- Lines should be under 80 characters where possible for screenshot-friendliness.253- **Language:** If `OUTPUT_LANG` is ja, write all roast lines, fix descriptions,254 summary text, and section labels in Japanese. Category names in the scorecard255 table and structural elements (box-drawing, header) remain in English.256 If `OUTPUT_LANG` is en, write everything in English.257258---259260## Output Format261262Generate output following this structure (adapt rows to active checkers):263264```265━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━266 🔥 ROAST MY CODE — REPORT CARD 🔥267 Level: {LEVEL} | Target: {TARGET_PATH}268━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━269270📊 OVERALL: {GRADE} ({SCORE}/100)271272┌─────────────────────────────────────┐273│ Category Score Grade │274├─────────────────────────────────────┤275│ Security {xx}/100 {G} │276│ Architecture {xx}/100 {G} │277│ Complexity {xx}/100 {G} │278│ TDD {xx}/100 {G} │279│ Type Safety {xx}/100 {G} │280│ Error Handling {xx}/100 {G} │281│ Naming {xx}/100 {G} │282│ Dead Code {xx}/100 {G} │283│ Performance {xx}/100 {G} │284│ Dependencies {xx}/100 {G} │285│ API Design {xx}/100 {G} │286│ Frontend {xx}/100 {G} │287│ Git Hygiene {xx}/100 {G} │288└─────────────────────────────────────┘289(Only show rows for active checkers)290291━━━ 🔥 FINDINGS ━━━━━━━━━━━━━━━━━━━━━━292293## {CATEGORY} ({SCORE}/100)294295### 🚨 {CHECK_NAME} [{SEVERITY}]296📍 {file_path}:{line}297> {code evidence or description}298299💬 "{ROAST_LINE}"300301🔧 Fix: {actionable fix description}302303---304305(Repeat for each finding, grouped by category)306307━━━ 📋 SUMMARY ━━━━━━━━━━━━━━━━━━━━━━━308309🏆 Top 3 Strengths:310 1. {strength}311 2. {strength}312 3. {strength}313314💀 Top 3 Priorities to Fix:315 1. {priority with file reference}316 2. {priority with file reference}317 3. {priority with file reference}318319📈 Quick Wins (< 5 min each):320 - {quick fix 1}321 - {quick fix 2}322 - {quick fix 3}323324━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━325 Roasted with ❤️ by roast-my-code326 ⭐ github.com/sakimyto/roast-my-code327━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━328```329330### Output Rules3313321. **Scorecard table** always appears first.3332. **Findings** are grouped by category, ordered by score334 (worst category first).3353. Within each category, findings are ordered: critical > error >336 warning > info.3374. **Summary** always appears last.3385. If a category scored 100 (no findings), show it in the table339 but skip the findings section for it. Add it to Strengths.3406. The roast line MUST match the selected LEVEL's tone from341 roast-style.md.3427. Every roast MUST be paired with a Fix.3438. Use box-drawing characters for the table exactly as shown.3449. If the overall grade is S, add a congratulatory roast:345 "I came here to roast, but your code left me speechless.346 Well played."347348---349350## Scoring Quick Reference351352| Severity | Deduction | Examples |353|----------|-----------|---------|354| critical | -20 | Hardcoded secrets, SQL injection, no tests |355| error | -10 | Empty catch, God files, `any` abuse |356| warning | -4 | console.log, TODO comments, inline styles |357| info | -1 | Missing engine field, no readonly |358359| Weight | Category | Multiplier | Note |360|--------|----------|-----------|------|361| High | Security | 1.5x | Always |362| Medium | Architecture | 1.2x | Always |363| Elevated | TDD | 1.5x | sensei mode only (1.0x otherwise) |364| Normal | All others | 1.0x | |365366**Note:** Weights apply ONLY to the overall weighted average, not to367individual category scores (which are always displayed out of 100).368Per-check cap: max 3 findings per check type count toward the score.369370| Grade | Range | Vibe |371|-------|-------|------|372| S | 90-100 | Ship it yesterday |373| A | 80-89 | Production-ready |374| B | 70-79 | Code review approved |375| C | 60-69 | Needs another pass |376| D | 40-59 | Intern's first week? |377| F | 0-39 | Call the fire department |