
Academic Paper Search Skill
A field-agnostic skill for searching scholarly papers from one machine. It queries
arXiv and Semantic Scholar without an API key, falls back to DuckDuckGo for web/GitHub
material, and downloads or extracts text from PDFs. The MCP servers
(arxiv-mcp-server, Ai2 Asta) are used automatically inside the current Claude Code
or Codex session when registered.
The examples below use placeholder topics (<your topic>, generic keyword strings).
Swap in your own research terms — nothing here is tied to a particular field.
This skill works in both Claude Code and Codex. Default install paths:
- Claude Code venv:
~/.claude/skill_venv/bin/python3 - Codex venv:
${CODEX_HOME:-~/.codex}/skill_venv/bin/python3
Use the path that matches the current host. When MCP tools are deferred, load them with
the host's native tool discovery (ToolSearch in Claude Code, tool_search in Codex).
When to use
- Searching for papers / scholarly material on any topic
- Searching or downloading from arXiv
- Citation / cited-by analysis via Semantic Scholar
- Extracting text or supplementary code from a PDF
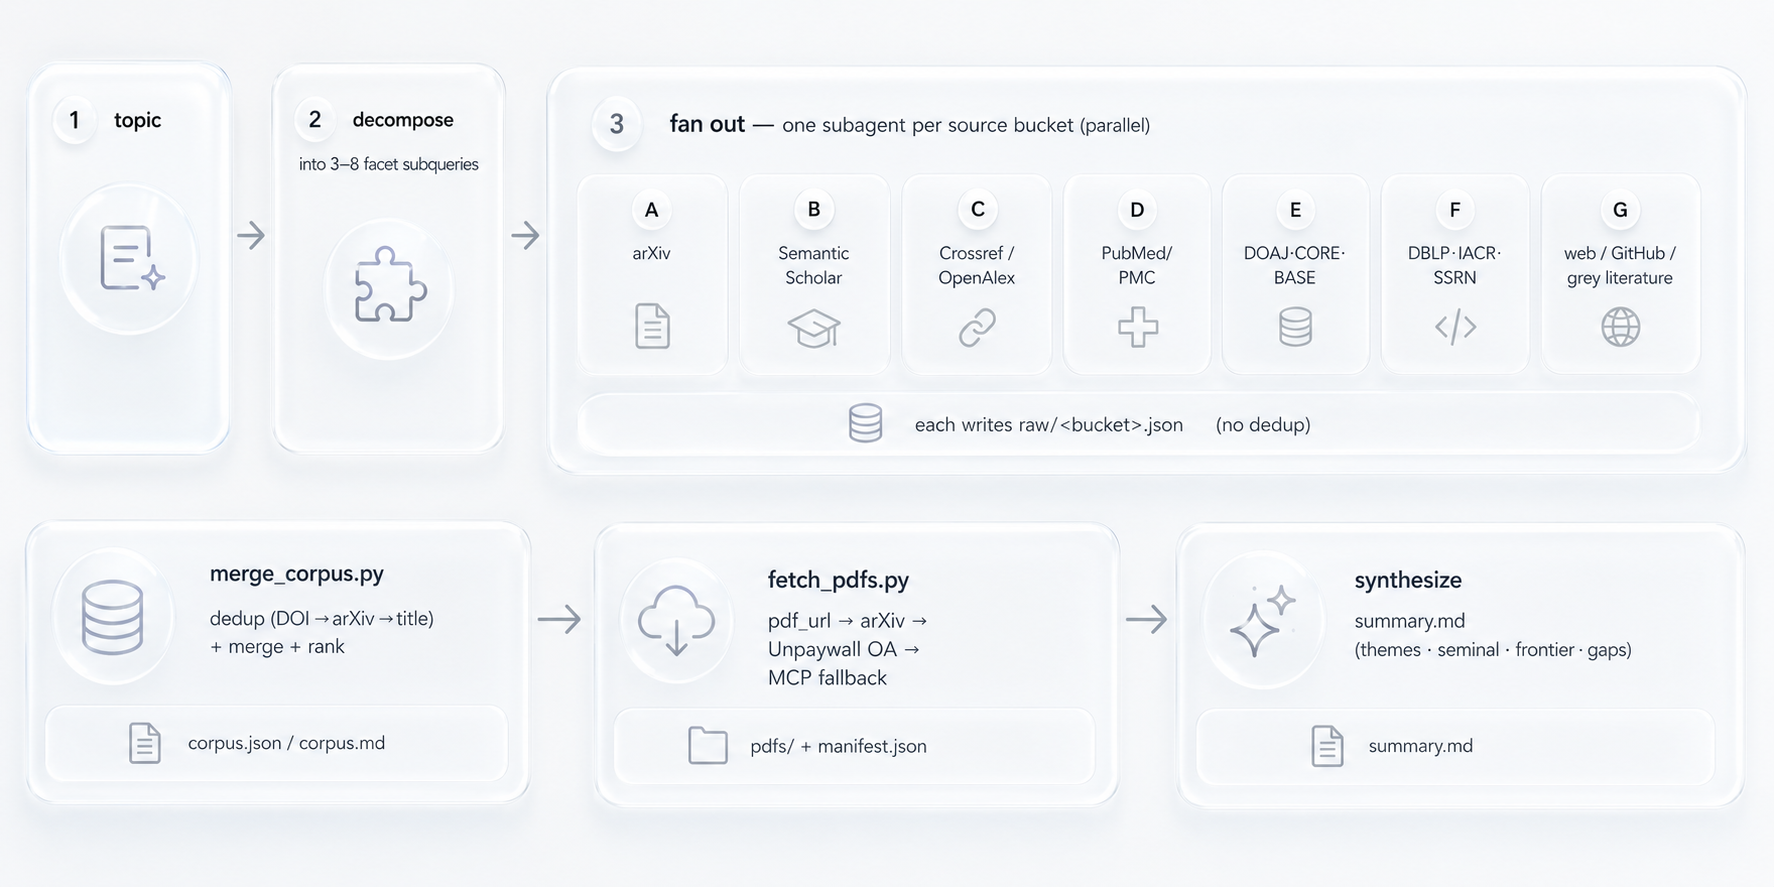
For an exhaustive, deduplicated sweep across 20+ databases, use the scholar-megasearch skill instead — this skill is for fast, single-source lookups.
Installed tools
| Tool | Path / method | Purpose |
|---|---|---|
arxiv Python package |
host skill_venv/bin/python3 |
arXiv search |
semanticscholar Python package |
host skill_venv/bin/python3 |
Semantic Scholar search |
arxiv-mcp-server |
registered MCP (uvx) | MCP tools |
asta (Ai2 Asta, remote) |
registered MCP | MCP tools |
paper-search-mcp |
host MCP venv | arXiv + SS + PubMed unified |
ddgs |
host skill_venv/bin/python3 |
DuckDuckGo fallback search |
pdfplumber |
host skill_venv/bin/python3 |
PDF text extraction |
crwl (crawl4ai) |
host skill_venv/bin/crwl |
Web crawling |
Core command patterns
1. arXiv search (recommended)
<host-skill-venv>/bin/python3 << 'EOF'
import arxiv, json

client = arxiv.Client()
search = arxiv.Search(
    query="<your topic keywords>",
    max_results=20,
    sort_by=arxiv.SortCriterion.Relevance
)
results = []
for r in client.results(search):
    results.append({
        "title": r.title,
        "authors": [str(a) for a in r.authors[:3]],
        "year": r.published.year,
        "arxiv_id": r.entry_id.split("/")[-1],
        "pdf_url": r.pdf_url,
        "categories": r.categories,
        "summary": r.summary[:300]
    })
print(json.dumps(results, indent=2, ensure_ascii=False))
EOF
2. Semantic Scholar search (200M+ papers)
<host-skill-venv>/bin/python3 << 'EOF'
from semanticscholar import SemanticScholar
import json

sch = SemanticScholar()
results = sch.search_paper(
    "<your topic keywords>",
    limit=20,
    fields=["title", "authors", "year", "externalIds", "openAccessPdf", "citationCount", "abstract"]
)
output = []
for p in results:
    output.append({
        "title": p.title,
        "year": p.year,
        "citations": p.citationCount,
        "doi": p.externalIds.get("DOI") if p.externalIds else None,
        "arxiv_id": p.externalIds.get("ArXiv") if p.externalIds else None,
        "pdf": p.openAccessPdf.get("url") if p.openAccessPdf else None,
        "abstract": (p.abstract or "")[:300]
    })
print(json.dumps(output, indent=2, ensure_ascii=False))
EOF
3. DuckDuckGo fallback search (GitHub, blogs, etc.)
<host-skill-venv>/bin/python3 << 'EOF'
from ddgs import DDGS
import json

results = DDGS().text(
    "site:github.com <your topic keywords>",
    max_results=15
)
print(json.dumps(results, indent=2, ensure_ascii=False))
EOF
4. Extract text from a PDF
<host-skill-venv>/bin/python3 << 'EOF'
import pdfplumber

with pdfplumber.open("paper.pdf") as pdf:
    for i, page in enumerate(pdf.pages):
        text = page.extract_text()
        if text:
            print(f"=== Page {i+1} ===")
            print(text[:500])
EOF
5. URL → markdown scraping
<host-skill-venv>/bin/crwl "https://arxiv.org/abs/2401.12345" -o markdown
6. Download an arXiv PDF
<host-skill-venv>/bin/python3 << 'EOF'
import arxiv, os

client = arxiv.Client()
paper = next(client.results(arxiv.Search(id_list=["2401.12345"])))
paper.download_pdf(dirpath="./papers/", filename="paper.pdf")
print(f"Downloaded: {paper.title}")
EOF
Using MCP (inside a host session)
arxiv-mcp-server and asta (Ai2 Asta, Semantic Scholar) are registered with the
current host. Inside a session, the MCP tools can be called automatically (load their
schemas with the host's tool discovery first when they are deferred).
Search strategy guide
Pick the tool that matches what you are after — the keyword strings are just placeholders for your own terms.
| Goal | Recommended tool | Example query |
|---|---|---|
| Latest arXiv preprints | arxiv package |
<topic> 2024 2025 |
| Highly-cited / canonical papers | Semantic Scholar | <topic> review survey |
| Code / implementations | ddgs site:github.com |
site:github.com <topic> |
| Published journal articles | Semantic Scholar + Crossref | <topic> <venue name> |
| Non-English material | ddgs |
a localized phrasing of <topic> |
Choosing arXiv categories
Filtering by category sharpens results. Pick the categories that match your field — the full taxonomy is at https://arxiv.org/category_taxonomy. A few common ones across disciplines:
cs.LG/cs.AI— machine learning / artificial intelligencecs.CL— computation and language (NLP)cs.CV— computer visionstat.ML— statistics: machine learningcond-mat.*— condensed matter physicsphysics.comp-ph— computational physicsq-bio.*— quantitative biologymath.*— mathematicseess.*— electrical engineering and systems science
# Filter to one or more categories and sort by most recent
search = arxiv.Search(
    query="cat:cs.LG AND <topic keywords>",
    max_results=20,
    sort_by=arxiv.SortCriterion.SubmittedDate
)