
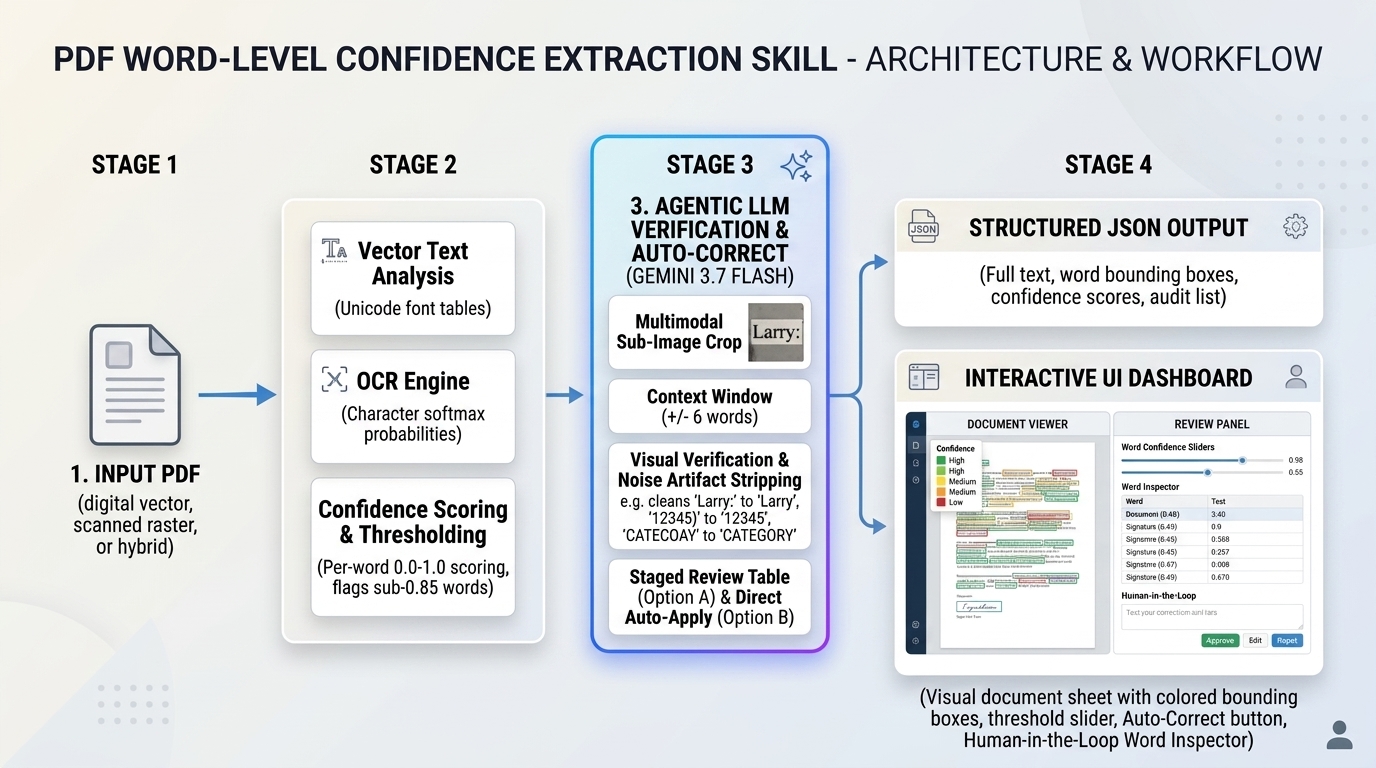
PDF Word-Level Confidence Extraction Skill
This skill provides an automated workflow to process PDF files, extract character and word tokens, compute normalized confidence scores (0.0 to 1.0) for every word, and generate a standardized JSON document.
Prerequisites and OCR Engine Setup
Digital vector PDFs work out-of-the-box with standard Python libraries. For scanned PDFs (raster images without a digital text layer), an OCR engine must be available:
- macOS (Homebrew):
brew install tesseract - Debian / Ubuntu / Docker:
sudo apt-get update && sudo apt-get install -y tesseract-ocr - Fedora / RHEL:
sudo dnf install -y tesseract - Windows (winget):
winget install UB-Mannheim.TesseractOCR - Python / Rootless Environments:
pip install rapidocr-onnxruntime(pure-Python ONNX engine requiring no system root permissions).
If Tesseract is installed in a non-standard path, specify it via the --tesseract-cmd /path/to/tesseract argument or set the TESSERACT_CMD environment variable.
Procedure for the Agent
Follow these sequential steps when a user requests PDF text extraction with confidence scoring.
Step 1: Identify Input PDF, Parameters, and OCR Availability
- Locate the relative path to the target PDF file requested by the user.
- Determine if the user specified a custom confidence threshold (default is 0.85).
- Determine if the user specified an extraction mode:
auto(default): Automatically detects digital text vs image/scanned pages.digital: Fast vector text extraction only.ocr: Optical character recognition on rendered page images.
- For scanned documents, verify OCR engine availability or pass
--tesseract-cmdif using a custom binary path. - Determine the target output JSON file path. If the user did not specify an output file, generate an output file named
<basename>_extracted.jsonin the same directory or current workspace.
Step 2: Execute the Extraction Script
Run the extraction script using the Python CLI tool. Important: Do NOT automatically pass --llm-correct or run automated LLM correction during standard document extraction. The skill must first extract text, compute confidence scores, and generate the UI dashboard so that the human reviewer can inspect flagged tokens and decide when to click the "Auto-Correct with Gemini" button in the dashboard interface.
python3 skills/pdf-extract-confidence/scripts/extract_pdf.py \
  --input "samples/104-10062-10073.pdf" \
  --output "samples/104-10062-10073_extracted.json" \
  --html-output "samples/104-10062-10073_dashboard.html" \
  --threshold 0.85 \
  --mode auto \
  --validate
(Note: --llm-correct is strictly an optional CLI flag reserved only for cases where the human user explicitly requests headless/batch AI correction without visual UI review).
Key CLI flags:
-i, --input PATH: Target input PDF file (required).-o, --output PATH: Output JSON file path.--html-output PATH: Generates a standalone interactive HTML dashboard embedding the extraction data.-t, --threshold FLOAT: Cutoff for low confidence flagging (default: 0.85).-m, --mode [auto|digital|ocr]: Extraction pipeline modality.--tesseract-cmd PATH: Custom path to the Tesseract executable if not in system PATH.--dpi INT: Rendering resolution for rasterizing pages before OCR (default: 200).--validate: Validates output against the resource schema.--compact: Generates compact unformatted JSON instead of indented formatting.--llm-correct: Enable agentic LLM (Gemini 3.8 Flash) word correction for low-confidence tokens.--gemini-api-key KEY: API Key for Gemini (defaults toGEMINI_API_KEYenvironment variable).--llm-model MODEL: Gemini model identifier (default:gemini-3.8-flash).--thinking-budget INT: Thinking budget token allocation for the reasoning model (default:2048, 0 to disable).--no-preprocess-patches: Disable morphological sub-image patch preprocessing for form element suppression.--llm-auto-apply: Automatically apply all LLM suggestions directly to the text and word array (Option B).--mock-llm: Offline heuristic mock mode for testing without API keys.
Step 3: Verify Output Integrity
- Check that the script completed with exit code 0.
- Read the output JSON file and verify the top-level sections:
metadata: Contains total_pages, total_words, mean_confidence, min_confidence, low_confidence_count, human_corrections_count, llm_corrections_count.full_text: Consolidated plain text for direct consumption.pages: Array of per-page objects containing text and word arrays.low_confidence_words: Array containing any words with confidence < threshold.llm_suggestions: Optional array of LLM audit recommendations.
Step 4: Visual UI Dashboard & Dual HITL / AI Review
Always generate the standalone dashboard file by including --html-output <basename>_dashboard.html in Step 2:
- The script bundles the HTML markup, CSS stylesheet, and extracted JSON payload into a self-contained single-file HTML dashboard that operates in any standard web browser or embedded viewer without external network requests or file uploading.
- The interactive UI dashboard provides:
- Human-Driven Inspection: Initial extraction displays original document text and confidence flags for human inspection without performing unprompted background AI modifications.
- On-Demand "Auto-Correct with Gemini": The human reviewer clicks the "Auto-Correct with Gemini" button in the dashboard header to initiate LLM analysis when desired.
- Staged AI Review Table (Option A - Default): Displays Gemini's suggested fixes, rationales, and an instant "Apply All Suggestions" button to minimize human-in-the-loop overhead.
- Direct Auto-Apply (Option B): Instantly applies LLM suggestions with an undo snapshot stack.
- Word Inspector AI Suggest: Ask Gemini for recommendations on individual selected tokens with 1-click accept.
- Dynamic Confidence Threshold Slider & Number Input: Real-time bounding box and token chip highlighting.
- Visual Document Overlays: Color-coded bounding boxes (green for high confidence, red for low confidence, purple for human-corrected, indigo for LLM-verified).
- Export Corrected JSON: Exports schema-compliant JSON preserving all human and AI corrections and audit metadata.
Step 5: Present Findings to the User
Provide a clean, structured summary containing:
- Document metadata (file name, total pages, total words extracted).
- Overall confidence metrics (mean confidence, minimum confidence).
- Audit summary: Number of low-confidence words detected.
- If low-confidence words exist, list the top flagged words with page number, confidence score, and explain that the human reviewer can inspect and trigger AI correction in the dashboard.
- Location of the generated JSON output file and interactive HTML dashboard.
Downstream Consumption Patterns
The generated JSON file accommodates two distinct downstream consumer types:
- Full-Text Consumers: Direct NLP or LLM ingestion can access the
full_textfield orpages[i].textwithout traversing word arrays. - Verification & Audit Consumers: Human-in-the-loop review systems can inspect
low_confidence_wordsor iterate overpages[i].wordsto render bounding boxes (bbox) over page images for interactive review.
Verification and Testing
To verify that the skill, its dependencies, and OCR engine are properly installed and functioning, run the standard library Python unit test suite:
python3 -m unittest discover -s tests -v
Or run individual test modules directly:
python3 tests/test_extractor.py
python3 tests/test_schema.py
python3 tests/test_llm_correction.py
References and Resources
- Extraction Script: extract_pdf.py
- LLM Correction Engine: llm_correction.py
- UI Dashboard Template: index.html
- UI Stylesheet: styles.css
- UI Application Logic: app.js
- Synthetic Sample Generator: generate_samples.py
- JSON Schema Definition: schema.json
- Sample Output Example: sample_output.json
- Confidence Methodology: confidence_scoring.md
- Cloud Engine Adapters: cloud_adapters.md
- Unit Tests: test_extractor.py, test_schema.py, and test_llm_correction.py