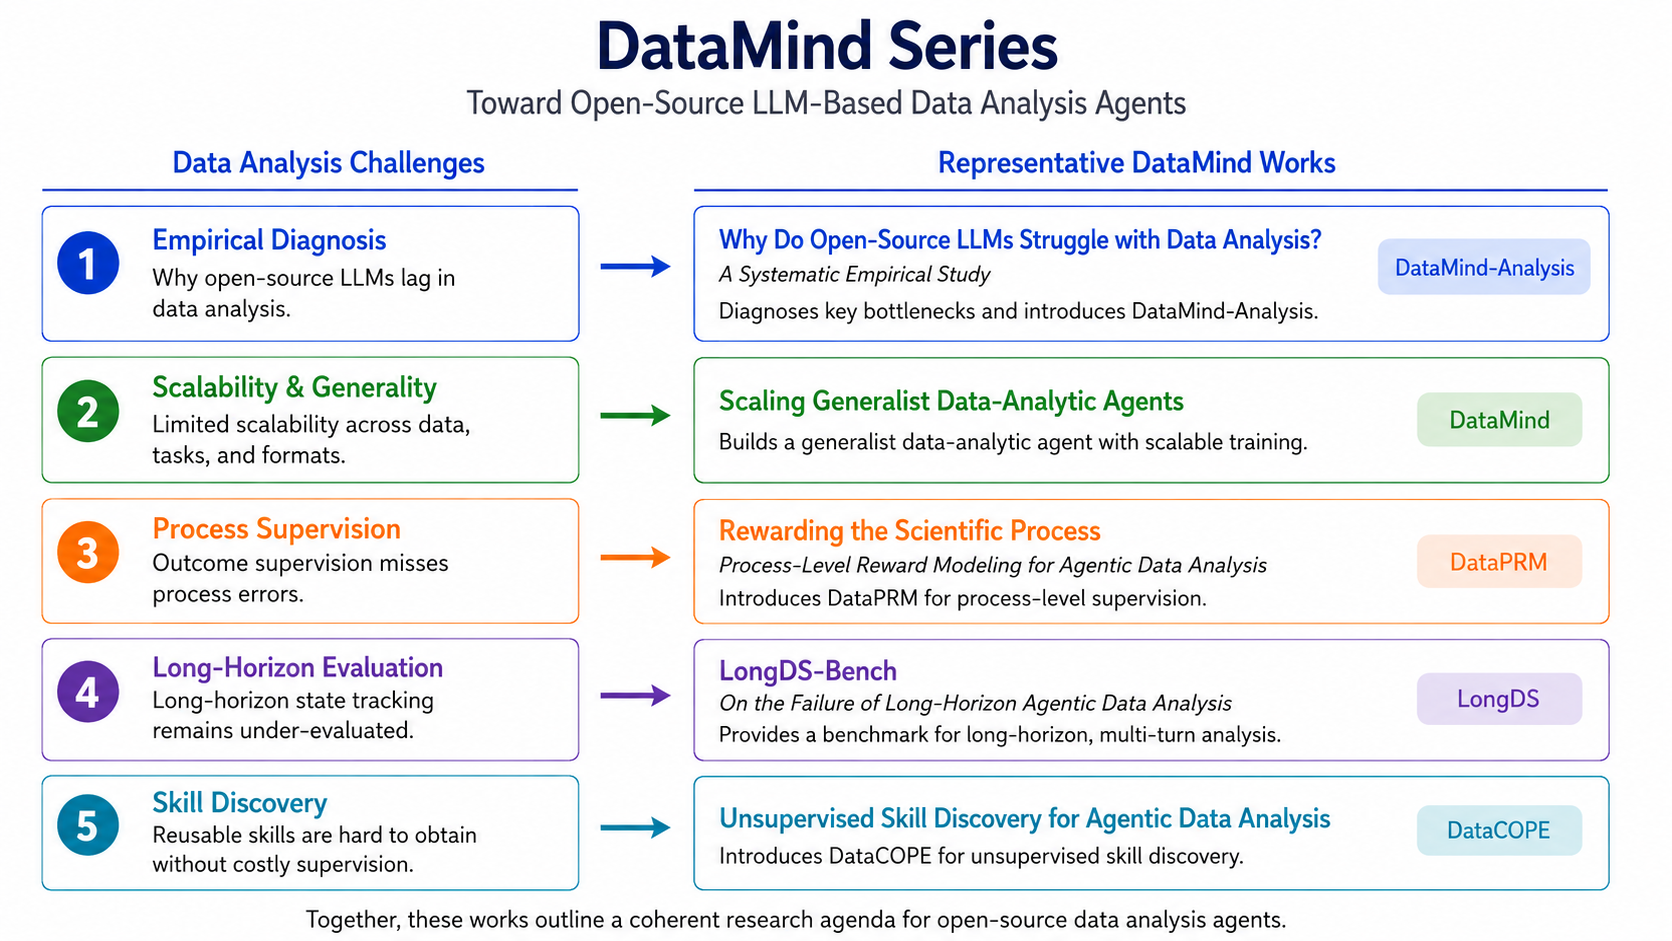
LongDS-Bench — the agent runs the benchmark on itself
The agent executing this skill is the runtime being measured. This skill does NOT install DSGym or its ~12 GB Docker executor, and does NOT download the dataset. It uses only the locally-prepared LongDS dataset and the official rules (turn protocol + LLM-judge). You read each task, do the multi-turn data analysis yourself with your shell tool and a persistent Python session, produce an answer per turn, then score yourself with the official judge prompt.
It is agent-agnostic: any harness with a shell/code-execution tool can run it. Written for a shell tool (no PTY, no interactive prompts). Run the heavy parts in the background if your harness supports it.
Prerequisite (operator does this once — see $SKILL_DIR/../README, not this skill): a prepared Conda environment named longds with the data-science stack, the dataset downloaded, and prepare_dataset.py run to produce the answer-stripped workspace. This skill assumes those prerequisites already exist and that VENV points to the Conda environment directory. If they do not, stop and point the user at $SKILL_DIR/../README.
Paths used below:
SKILL_DIR — where this skill is installed (its scripts/ holds prepare_dataset.py, pysession.py, judge.py).RUN — the prepared workspace: contains index.json, manifest/, gold/, answers/.VENV — the prepared Conda environment directory. Run every Python command with "$VENV/bin/python"; do not activate or modify the environment during the benchmark.
Upstream (read if anything drifts): https://github.com/zjunlp/DataMind/tree/main/longds and https://huggingface.co/datasets/zjunlp/LongDS
What is measured
68 tasks / 2,225 turns across six domains (Business, Community, Education, Geoscience, Social Good, Sports). Each task is ONE continuous multi-turn conversation where analytical state evolves (state inheritance, update, counterfactual perturbation, rollback, multi-state composition). Per turn the agent gets context + question and must produce a final answer; the judge scores each turn 0/1 and the mean over all turns is the accuracy. Best published model ≈ 48.45 (Gemini-3.1-Pro); GPT-5.4 43.50; Claude-4.6-Sonnet 41.56.
Integrity rules (do not cheat — read first)
- Solve only from the manifest (
$RUN/manifest/<key>.json: turn_id, context, question, data_dir).
- NEVER open
$RUN/gold/, nor any raw task.json / task.py / task.ipynb in the dataset tree, while solving. Those carry the reference answer/solution and are held out for the judge only. (If the operator ran prepare_dataset.py --strip-source, those files are already deleted from the dataset tree.)
- Treat the manifest's
data_dir as read-only input. Never create, modify, rename, or delete files there. Write scripts, caches, derived files, and other intermediates only under $RUN/workspace/<key>/.
- Solve turns strictly in
turn_id order. Do not look ahead to later turns before answering the current one.
- One persistent Python session per task; do not reset it between turns of the same task (state continuity is the whole point).
Cost & safety
Thousands of reasoning steps + paid judge calls; a full run can take many hours. So:
- Always start with a tiny slice (one task, few turns) end-to-end (solve → judge) before scaling.
- Confirm scope with the user before a full run. State the rough cost/time.
- Run the full evaluation in the background (if supported) and checkpoint per task so a crash loses at most one task.
The agent loop (the rules — follow exactly)
Read $RUN/index.json. For each task, in order:
- Read its manifest
$RUN/manifest/<key>.json (turns + data_dir). Do not open gold / raw task files.
- Create a task-specific scratch directory and start one persistent session there. Do not use
data_dir as the current working directory:mkdir -p "$RUN/workspace/<key>"
"$VENV/bin/python" "$SKILL_DIR/scripts/pysession.py" start \
--conn "$RUN/sess/<key>.json" --pidfile "$RUN/sess/<key>.pid" \
--cwd "$RUN/workspace/<key>" # run in background
- For each turn (ascending
turn_id), act as an expert data scientist (this is the benchmark's system-prompt role):
- In the first Python block, set
DATA_DIR = Path("<data_dir>").resolve() from the manifest and WORK_DIR = Path.cwd(). Read source files through DATA_DIR; direct every write to WORK_DIR.
- You receive
{context}\nQuestion: {question}. Plan, then work in single-step Python blocks. Execution is continuous — variables/data from earlier steps and earlier turns persist; do not reload data you already loaded.
- Each step: write the code block to a file and run it through the SAME session, feed the output back into your reasoning, iterate (cap ~40 steps/turn):
printf '%s' "$CODE" > "$RUN/workspace/<key>/step.py"
"$VENV/bin/python" "$SKILL_DIR/scripts/pysession.py" exec --conn "$RUN/sess/<key>.json" \
  --code-file "$RUN/workspace/<key>/step.py" --timeout 300
- Rules from the benchmark's system prompt: no plotting (text summaries/statistics only); use Python for any calculation; give the exact numeric value requested; produce the answer only once you have validated evidence. The session
cwd is the task's scratch workspace; source data remains under the read-only DATA_DIR path.
- When done with the turn, record your final answer (specific, directly answering the question — the equivalent of the official
<answer> content) by appending to $RUN/answers/<key>.json:{"key":"<key>","domain":"<domain>","dataset":"<dataset>","task_id":"<task_id>",
"answers":[{"turn_id":1,"answer":"..."},{"turn_id":2,"answer":"..."}]}
- Stop the session:
"$VENV/bin/python" "$SKILL_DIR/scripts/pysession.py" stop --pidfile "$RUN/sess/<key>.pid".
To resume after a crash, skip tasks whose $RUN/answers/<key>.json already has all turns.
Scale / orchestration
A full run is large. Prefer, in order of what your harness supports:
- One worker/subagent per task (focused context, its own session); the controller keeps
index.json, dispatches tasks, and never holds all 68 tasks in one context.
- Background execution with per-task checkpointing to
answers/.
- A small pilot (a few tasks) first; report its score before committing to all 68.
Scoring
After answers exist, run the official judge (separate judge endpoint via JUDGE_API_KEY / JUDGE_BASE_URL; default model deepseek-v4-pro):
export JUDGE_API_KEY="<key>"; export JUDGE_BASE_URL="https://api.deepseek.com"
"$VENV/bin/python" "$SKILL_DIR/scripts/judge.py" --answers "$RUN/answers" --gold "$RUN/gold" \
  --out "$RUN/results_eval.json" --judge-model "deepseek-v4-pro" --max-workers 8
judge.py joins answers↔gold by turn_id, scores each turn 0/1 with the verbatim JUDGE_PROMPT, and prints overall accuracy + per-domain accuracy. Report those to the user against the paper's numbers.
Honesty caveats (state these in the final report)
- Not officially comparable. This uses a local Conda environment instead of DSGym's pinned Docker image, and the agent's own loop instead of the benchmark's fixed ReAct scaffold. Treat the number as indicative of the agent's ability, not a leaderboard-equivalent score.
- Judge bias. Prefer a judge model/endpoint different from the model powering the agent under test. If you must self-judge, say so — self-judging inflates scores.
- Report turns that failed to execute or were skipped; do not silently count them as 0 without noting it.
Failure handling
- Prereqs absent (
$VENV/bin/python is missing or not executable / no $RUN/index.json): the Conda environment or dataset workspace was not prepared — stop and direct the user to $SKILL_DIR/../README. Do not download the 19.5 GB dataset from inside the run.
data_dir_exists: false in index.json: the dataset download was partial; the operator must re-download (or prepare_dataset.py was run against an incomplete tree).ModuleNotFoundError in a turn: do not modify the environment during the benchmark. Report the missing package so the operator can install it into the longds Conda environment, then restart that task from turn 1.- Kernel not ready / dead (
pysession exec exits 2 / "kernel died"): restart the session for that task; you lose only that task's in-session state — restart the task from turn 1.
- Step exceeds
--timeout: tighten the code or raise --timeout; do not let a runaway step stall the whole run.
- Judge can't parse
<score>: it retries 3× then records score: null; those turns are excluded from the average and reported as unjudged.
- Upstream drift: the canonical judge prompt lives in
runners/src/judge_prompt.py; the DSGym turn protocol lives in runners/DSGym/scripts/longds.py; re-read them if results look off.
1---2name: longds-bench3description: "Self-evaluate the current agent on LongDS-Bench (zjunlp/DataMind): the long-horizon, multi-turn agentic data-analysis benchmark. Use this when the user asks to run, score, or benchmark an agent on LongDS / LongDS-Bench / DataMind longds, or to measure multi-turn data-analysis ability. This does NOT use DSGym's Docker runtime — the agent running this skill IS the agent under test: it reads a locally-prepared dataset, performs the multi-turn analysis with its own tools, and is scored by the official LLM-judge rule. The ~19.5 GB dataset must be downloaded and prepared by the operator beforehand (see `$SKILL_DIR/../README`); this skill does not download it. Heavyweight and long-running; run in the background if supported and confirm scope first."4license: MIT5---67# LongDS-Bench — the agent runs the benchmark on itself89**The agent executing this skill is the runtime being measured.** This skill does NOT install DSGym or its ~12 GB Docker executor, and does NOT download the dataset. It uses only the locally-prepared LongDS **dataset** and the official **rules** (turn protocol + LLM-judge). You read each task, do the multi-turn data analysis yourself with your `shell` tool and a persistent Python session, produce an answer per turn, then score yourself with the official judge prompt.1011It is agent-agnostic: any harness with a shell/code-execution tool can run it. Written for a `shell` tool (no PTY, no interactive prompts). Run the heavy parts in the background if your harness supports it.1213**Prerequisite (operator does this once — see `$SKILL_DIR/../README`, not this skill):** a prepared Conda environment named `longds` with the data-science stack, the dataset downloaded, and `prepare_dataset.py` run to produce the answer-stripped workspace. This skill assumes those prerequisites already exist and that `VENV` points to the Conda environment directory. If they do not, stop and point the user at `$SKILL_DIR/../README`.1415Paths used below:16- `SKILL_DIR` — where this skill is installed (its `scripts/` holds `prepare_dataset.py`, `pysession.py`, `judge.py`).17- `RUN` — the prepared workspace: contains `index.json`, `manifest/`, `gold/`, `answers/`.18- `VENV` — the prepared Conda environment directory. Run every Python command with `"$VENV/bin/python"`; do not activate or modify the environment during the benchmark.1920Upstream (read if anything drifts): https://github.com/zjunlp/DataMind/tree/main/longds and https://huggingface.co/datasets/zjunlp/LongDS2122## What is measured232468 tasks / 2,225 turns across six domains (Business, Community, Education, Geoscience, Social Good, Sports). Each task is ONE continuous multi-turn conversation where analytical state evolves (state inheritance, update, counterfactual perturbation, rollback, multi-state composition). Per turn the agent gets `context` + `question` and must produce a final answer; the judge scores each turn **0/1** and the mean over all turns is the accuracy. Best published model ≈ **48.45** (Gemini-3.1-Pro); GPT-5.4 43.50; Claude-4.6-Sonnet 41.56.2526## Integrity rules (do not cheat — read first)2728- Solve only from the **manifest** (`$RUN/manifest/<key>.json`: `turn_id`, `context`, `question`, `data_dir`).29- **NEVER** open `$RUN/gold/`, nor any raw `task.json` / `task.py` / `task.ipynb` in the dataset tree, while solving. Those carry the reference answer/solution and are held out for the judge only. (If the operator ran `prepare_dataset.py --strip-source`, those files are already deleted from the dataset tree.)30- Treat the manifest's `data_dir` as read-only input. Never create, modify, rename, or delete files there. Write scripts, caches, derived files, and other intermediates only under `$RUN/workspace/<key>/`.31- Solve turns strictly in `turn_id` order. Do not look ahead to later turns before answering the current one.32- One persistent Python session per task; do not reset it between turns of the same task (state continuity is the whole point).3334## Cost & safety3536Thousands of reasoning steps + paid judge calls; a full run can take many hours. So:371. **Always start with a tiny slice** (one task, few turns) end-to-end (solve → judge) before scaling.382. **Confirm scope with the user before a full run.** State the rough cost/time.393. Run the full evaluation in the background (if supported) and checkpoint per task so a crash loses at most one task.4041## The agent loop (the rules — follow exactly)4243Read `$RUN/index.json`. For each task, in order:44451. Read its manifest `$RUN/manifest/<key>.json` (turns + `data_dir`). Do not open gold / raw task files.462. Create a task-specific scratch directory and start one persistent session there. Do not use `data_dir` as the current working directory:47 ```bash48 mkdir -p "$RUN/workspace/<key>"49 "$VENV/bin/python" "$SKILL_DIR/scripts/pysession.py" start \50 --conn "$RUN/sess/<key>.json" --pidfile "$RUN/sess/<key>.pid" \51 --cwd "$RUN/workspace/<key>" # run in background52 ```533. For each turn (ascending `turn_id`), act as an expert data scientist (this is the benchmark's system-prompt role):54 - In the first Python block, set `DATA_DIR = Path("<data_dir>").resolve()` from the manifest and `WORK_DIR = Path.cwd()`. Read source files through `DATA_DIR`; direct every write to `WORK_DIR`.55 - You receive `{context}\nQuestion: {question}`. Plan, then work in **single-step** Python blocks. Execution is **continuous** — variables/data from earlier steps and earlier turns persist; do not reload data you already loaded.56 - Each step: write the code block to a file and run it through the SAME session, feed the output back into your reasoning, iterate (cap ~40 steps/turn):57 ```bash58 printf '%s' "$CODE" > "$RUN/workspace/<key>/step.py"59 "$VENV/bin/python" "$SKILL_DIR/scripts/pysession.py" exec --conn "$RUN/sess/<key>.json" \60 --code-file "$RUN/workspace/<key>/step.py" --timeout 30061 ```62 - Rules from the benchmark's system prompt: **no plotting** (text summaries/statistics only); use Python for any calculation; give the **exact** numeric value requested; produce the answer only once you have validated evidence. The session `cwd` is the task's scratch workspace; source data remains under the read-only `DATA_DIR` path.63 - When done with the turn, record your final answer (specific, directly answering the question — the equivalent of the official `<answer>` content) by appending to `$RUN/answers/<key>.json`:64 ```json65 {"key":"<key>","domain":"<domain>","dataset":"<dataset>","task_id":"<task_id>",66 "answers":[{"turn_id":1,"answer":"..."},{"turn_id":2,"answer":"..."}]}67 ```684. Stop the session: `"$VENV/bin/python" "$SKILL_DIR/scripts/pysession.py" stop --pidfile "$RUN/sess/<key>.pid"`.6970To resume after a crash, skip tasks whose `$RUN/answers/<key>.json` already has all turns.7172## Scale / orchestration7374A full run is large. Prefer, in order of what your harness supports:75- **One worker/subagent per task** (focused context, its own session); the controller keeps `index.json`, dispatches tasks, and never holds all 68 tasks in one context.76- **Background execution** with per-task checkpointing to `answers/`.77- A small pilot (a few tasks) first; report its score before committing to all 68.7879## Scoring8081After answers exist, run the official judge (separate judge endpoint via `JUDGE_API_KEY` / `JUDGE_BASE_URL`; default model `deepseek-v4-pro`):8283```bash84export JUDGE_API_KEY="<key>"; export JUDGE_BASE_URL="https://api.deepseek.com"85"$VENV/bin/python" "$SKILL_DIR/scripts/judge.py" --answers "$RUN/answers" --gold "$RUN/gold" \86 --out "$RUN/results_eval.json" --judge-model "deepseek-v4-pro" --max-workers 887```8889`judge.py` joins answers↔gold by `turn_id`, scores each turn 0/1 with the verbatim `JUDGE_PROMPT`, and prints overall accuracy + per-domain accuracy. Report those to the user against the paper's numbers.9091## Honesty caveats (state these in the final report)9293- **Not officially comparable.** This uses a local Conda environment instead of DSGym's pinned Docker image, and the agent's own loop instead of the benchmark's fixed ReAct scaffold. Treat the number as indicative of the agent's ability, not a leaderboard-equivalent score.94- **Judge bias.** Prefer a judge model/endpoint different from the model powering the agent under test. If you must self-judge, say so — self-judging inflates scores.95- Report turns that failed to execute or were skipped; do not silently count them as 0 without noting it.9697## Failure handling9899- **Prereqs absent** (`$VENV/bin/python` is missing or not executable / no `$RUN/index.json`): the Conda environment or dataset workspace was not prepared — stop and direct the user to `$SKILL_DIR/../README`. Do not download the 19.5 GB dataset from inside the run.100- **`data_dir_exists: false`** in index.json: the dataset download was partial; the operator must re-download (or `prepare_dataset.py` was run against an incomplete tree).101- **`ModuleNotFoundError` in a turn**: do not modify the environment during the benchmark. Report the missing package so the operator can install it into the `longds` Conda environment, then restart that task from turn 1.102- **Kernel not ready / dead** (`pysession exec` exits 2 / "kernel died"): restart the session for that task; you lose only that task's in-session state — restart the task from turn 1.103- **Step exceeds `--timeout`**: tighten the code or raise `--timeout`; do not let a runaway step stall the whole run.104- **Judge can't parse `<score>`**: it retries 3× then records `score: null`; those turns are excluded from the average and reported as unjudged.105- **Upstream drift**: the canonical judge prompt lives in `runners/src/judge_prompt.py`; the DSGym turn protocol lives in `runners/DSGym/scripts/longds.py`; re-read them if results look off.